gen‑ai.news

Archive

Every story we have published on generative image and video AI, newest first. 500 stories across 21 pages.

Looking for something specific? Search the archive · Browse by issue

Maket launches floor and wall textures from text or images
Image

Maket launches floor and wall textures from text or images

Maket, an AI-assisted architectural design tool, has added the ability to generate floor and wall textures directly from text prompts or reference images. The feature gives designers a faster way to explore material options within their existing workflow. It represents a natural expansion of Maket's generative toolset into the domain of surface and finish design.

Video

Best AI Video Generation Models in 2026: Elo, Price per Second, Open Weights

The AI video generation landscape has shifted considerably over the past year, with native audio, longer clip lengths, and open-weights models now firmly part of the competitive field. A November 2026 ranking from Artificial Analysis's blind human-preference Elo arena pairs quality scores with API pricing to give a clearer picture of where each model stands. The result is a leaderboard that looks notably different from what it did in late 2025.

AI Ambition: ArtCraft Cloned Photoshop and Now Wants to "Rebuild Everything"
Image

AI Ambition: ArtCraft Cloned Photoshop and Now Wants to "Rebuild Everything"

ArtCraft made waves by using AI to build an open-source reimagining of Photoshop, and CEO Brandon Thomas says that is only the beginning. The company's broader ambition is to challenge the closed, proprietary systems that dominate creative software and the web. It is a bold long-term goal, rooted in the idea that AI can lower the barrier to rebuilding complex software from scratch.

5 new Google Flow Tools designed by visual artists
Video

5 new Google Flow Tools designed by visual artists

Google has added five new tools to Flow, its AI-powered filmmaking platform, developed with input from working filmmakers and visual artists. The additions are aimed at giving creators more precise control over how their stories are visualized and produced. Each tool addresses a specific stage or challenge in the visual storytelling process.

Runway News | Closing the Gap Between Policy and Practice
Video

Runway News | Closing the Gap Between Policy and Practice

Runway has updated its content moderation policies to permit a broader range of dramatic and genre fiction content - including sword fights, shootouts, and horror - while keeping firm limits around genuine harm. The changes reflect an effort to bring the platform's written rules closer in line with what its systems actually allow in practice. Users can also now flag cases where moderation gets it wrong.

Premiere on PC Gets a Boost as Adobe and Microsoft Announce Expansion of Partnership
Video

Premiere on PC Gets a Boost as Adobe and Microsoft Announce Expansion of Partnership

Adobe and Microsoft have deepened their partnership to bring better-optimized versions of Photoshop, Premiere, After Effects, and Substance 3D Painter to high-performance Windows PCs. The expansion also includes Adobe Express capabilities coming to Microsoft Photos, with a preview for Windows Insiders expected in December. The move is tied to a separate Adobe-NVIDIA collaboration centered on RTX Spark-powered hardware.

Image

Phota Labs uses AI to turn everyday photos into professional-looking shots

Phota Labs is a new AI-powered service that automatically processes ordinary photos into polished, professional-looking images without requiring users to touch an editing tool. Rather than layering more manual controls onto an already crowded market, the company focuses on automating the entire editing pipeline. The goal is to make quality photo output accessible to people who have no background in photography or post-processing.

Avid Moves Into the AI Age With Its Ready to Play for Avid Media Composer
Video

Avid Moves Into the AI Age With Its Ready to Play for Avid Media Composer

Avid has launched Ready to Play, a suite of AI-assisted tools built into Media Composer using Google Gemini. The update introduces three core capabilities - creating, analyzing, and modifying video - designed to help editors maintain momentum without ceding creative control. It is available now as a free add-on for existing Media Composer subscribers.

Customer Tried to Scam LA Pizza Shop With AI Image
Image

Customer Tried to Scam LA Pizza Shop With AI Image

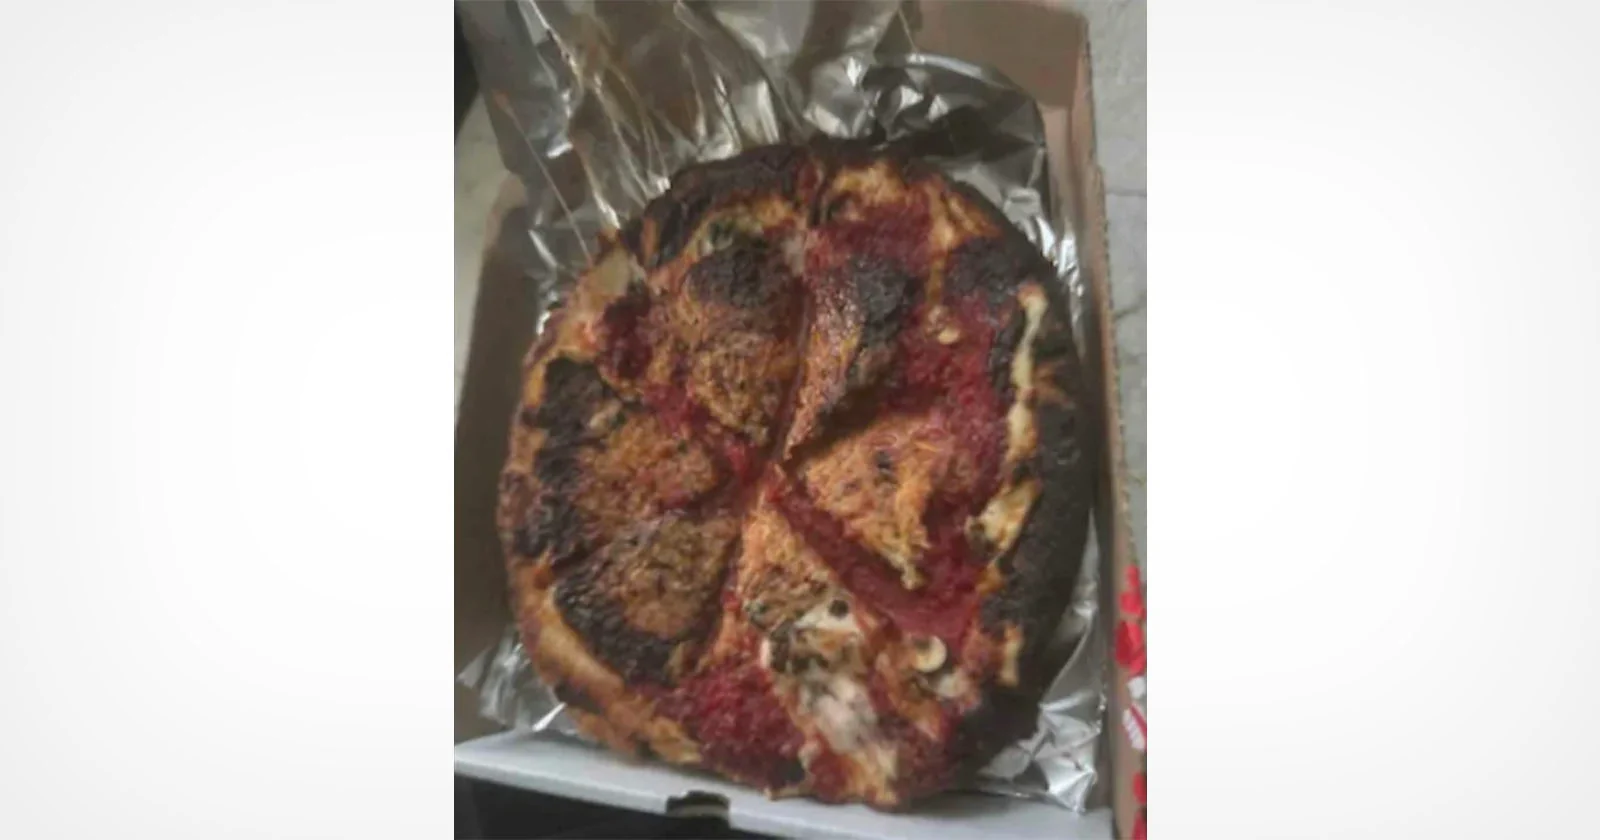
A customer at a Los Angeles pizza shop attempted to use an AI-edited photo of their order to claim a refund, but the scheme did not succeed. The incident highlights a growing concern for small businesses as image generation and editing tools become more accessible. It is a early real-world example of AI-fabricated evidence being used in a consumer dispute.

What Is MAX Sneaks? Your First Look at Tools That Don’t Exist Yet
Multimodal

What Is MAX Sneaks? Your First Look at Tools That Don’t Exist Yet

Adobe MAX Sneaks is an annual event where Adobe researchers demo experimental technology that has not yet made it into any product. Some of these demos eventually become familiar tools in Premiere, After Effects, or Photoshop - others never ship at all. This year's Sneaks airs Wednesday, November 11, and is free to watch online.

Adobe’s AI experiments let you walk around in photos and interview your characters
Multimodal

Adobe’s AI experiments let you walk around in photos and interview your characters

Adobe's annual Max conference has brought a fresh batch of experimental features, including tools that convert flat photos into navigable 3D scenes, let creators shape AI characters through conversation, and simplify photo editing to a copy-and-paste workflow. These "Sneaks" projects offer a glimpse into where Adobe's generative AI research is heading. None are shipping products yet, but they reflect the direction of the company's broader creative toolset.

Video

MBZUAI’s IFM Releases PAN 2, an Open 29B World Model for Physical AI

MBZUAI's Institute of Foundation Models has released PAN 2, an open-weight world model designed for physical AI applications. The system pairs a language model planner with a 29-billion-parameter diffusion transformer to simulate the visual outcomes of actions as video clips of up to 20 seconds. It is released under the permissive Apache 2.0 license, making it freely available for research and commercial use.

VSCO Updates Its Policy to Explicitly State It Won’t Train AI on Your Photos
Image

VSCO Updates Its Policy to Explicitly State It Won’t Train AI on Your Photos

VSCO has updated its Terms of Use to explicitly state that it does not and will not use user photos to train generative AI or machine learning models. The move comes months after vague policy language raised concerns among photographers and creators on the platform. The clarification offers a clearer commitment than the previous wording provided.

Tom Hanks Played Five Characters in This 2004 Christmas Movie
Multimodal

Tom Hanks Played Five Characters in This 2004 Christmas Movie

The Polar Express, Robert Zemeckis's 2004 performance-capture film, is back in seasonal rotation - and it remains one of the more technically unusual productions of its era. Tom Hanks played five distinct characters across 38 days of work, a casting choice that was rooted in story logic as much as technical curiosity. Here is a closer look at how that decision came together and what it meant for the actors involved.

MiniMax H3-Image: Bringing 4K Image Generation into the 10-Second Era - MiniMax Research
Image

MiniMax H3-Image: Bringing 4K Image Generation into the 10-Second Era - MiniMax Research

MiniMax has released H3-Image, an open-weight image generation model capable of producing 4K images in roughly 10 seconds. The model supports text-to-image generation, reference-based generation, and image editing within a single architecture. Built on MiniMax's H3 foundation, it marks the company's entry into the open-weight visual generation space.

Introducing the Multimodal Knowledge Agent benchmark
Multimodal

Introducing the Multimodal Knowledge Agent benchmark

Google has introduced the Multimodal Knowledge Agent (MKA) benchmark, a new evaluation framework designed to test how AI agents reason through visually complex, multimodal tasks. Unlike simpler benchmarks, MKA focuses on the kind of layered reasoning required when an agent must draw on both visual and textual information simultaneously. The release signals growing interest in more rigorous, real-world testing standards for multimodal AI systems.

Adobe is going all in on agentic AI
Multimodal

Adobe is going all in on agentic AI

At its Max conference in Miami, Adobe outlined a broad push toward agentic AI, positioning chatbots and autonomous agents as potential collaborators in creative workflows. New features span Firefly, Creative Cloud, and third-party integrations - pointing to a future where repetitive design tasks can run largely on their own. The announcements signal a meaningful shift in how Adobe imagines its tools being used day to day.

Instagram’s Effect Builder makes new filters from AI prompts
Image

Instagram’s Effect Builder makes new filters from AI prompts

Instagram has launched Effect Builder, a tool that lets US users create custom Stories filters by describing them in plain text prompts. The feature also accepts style reference images and allows iterative refinements through follow-up prompts. It is available now for users aged 18 and over in the United States.

How to Turn Your Live-Action Short Into a Stylized Rotoscope-Animated Film
Video

How to Turn Your Live-Action Short Into a Stylized Rotoscope-Animated Film

GIANTS, a five-minute animated short screening at this year's Austin Film Festival, began as a live-action shoot in 2013 before filmmaker Nate Bayless transformed it into a stylized rotoscope-animated film over a decade later. The project is a case study in patience, creative reinvention, and the particular appeal of rotoscoping as a medium that sits between live-action and animation. No Film School spoke with Bayless about the film's long journey and what finally brought it to the screen.

Adobe MAX Kicks Off This Week as Company Shares Stats on Accelerating AI Use
Multimodal

Adobe MAX Kicks Off This Week as Company Shares Stats on Accelerating AI Use

Adobe MAX kicks off this week in Miami, and ahead of the conference the company has released its 2026 Creators' Toolkit Report, surveying over 2,000 US creators on how AI is shaping their workflows. The data shows broad adoption, with 78% of creators using AI tools reporting accelerated business or audience growth. Major announcements about AI integrations across Creative Cloud are expected throughout the week.

Disney and Adobe are building generative AI tools together
Multimodal

Disney and Adobe are building generative AI tools together

Disney and Adobe have announced a multiyear partnership to develop proprietary generative AI models tailored to Disney's creative and production needs. The collaboration, revealed at Adobe's MAX conference, spans properties from theme parks and cruise lines to ESPN content. The models are described as "artist-led," with a focus on responsible AI development.

More Realistic Images More Stable Editing Across 100 Rounds Introducing Seedream 5 5
Image

More Realistic Images More Stable Editing Across 100 Rounds Introducing Seedream 5 5

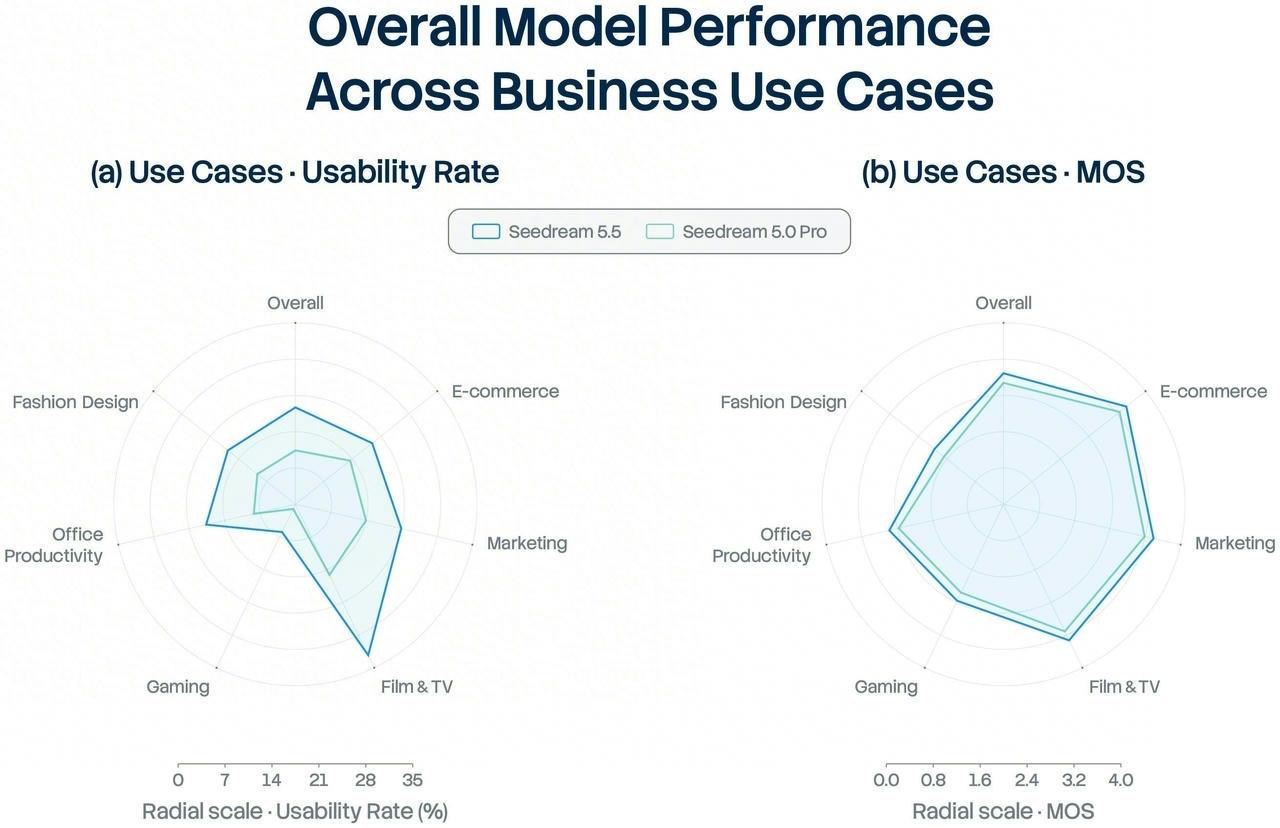
ByteDance has released Seedream 5.5, an update to its generative image model that focuses on two areas: improved photorealism and more consistent multi-round editing. The model claims stable output across up to 100 rounds of iterative editing, a significant step for workflows that require repeated refinement without drift.

Generate longer AI videos with Omni 1.2 Flash in Google Vids at no cost.
Video

Generate longer AI videos with Omni 1.2 Flash in Google Vids at no cost.

Google has updated its Vids app with the Omni 1.2 Flash model, allowing users to generate longer AI video clips of up to 15 seconds at no cost. The update also brings improved consistency across scenes, making it easier to produce cohesive video content. This marks a meaningful step forward in Google's effort to integrate generative video tools into its Workspace productivity suite.

New NVIDIA Cosmos 3 Open Models for Interactive World Simulation
Video

New NVIDIA Cosmos 3 Open Models for Interactive World Simulation

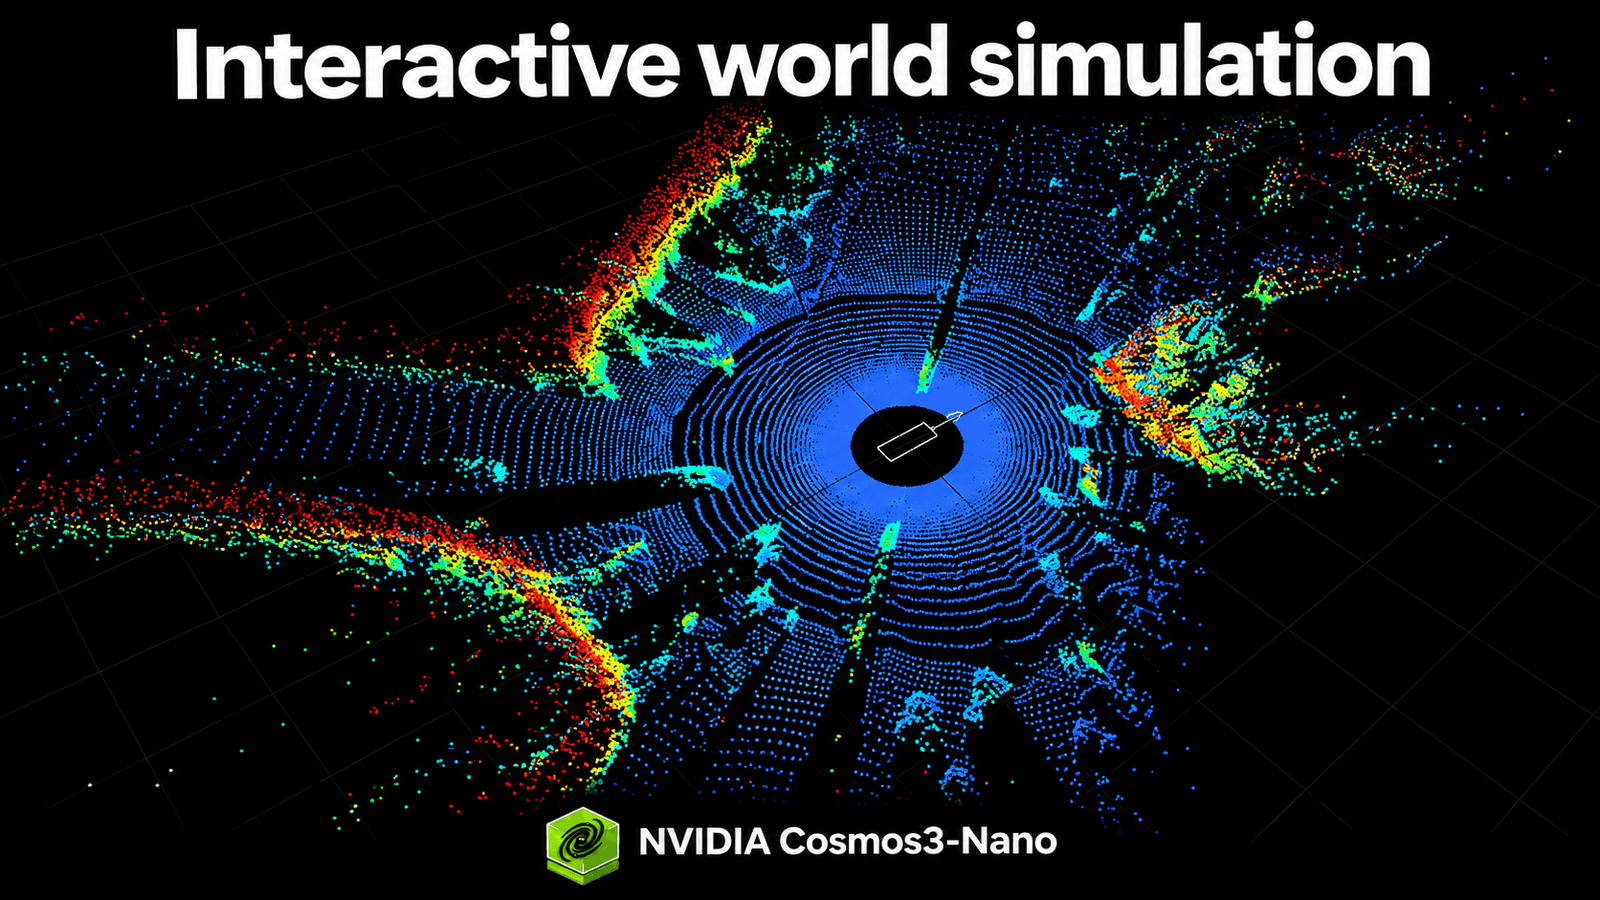
NVIDIA has released Cosmos 3, a new set of open models designed for interactive world simulation. The models are hosted on Hugging Face and represent a step forward in physically grounded, controllable video generation for robotics and autonomous systems research.