Meta built an AI detection tool to ID images and video created with its new models
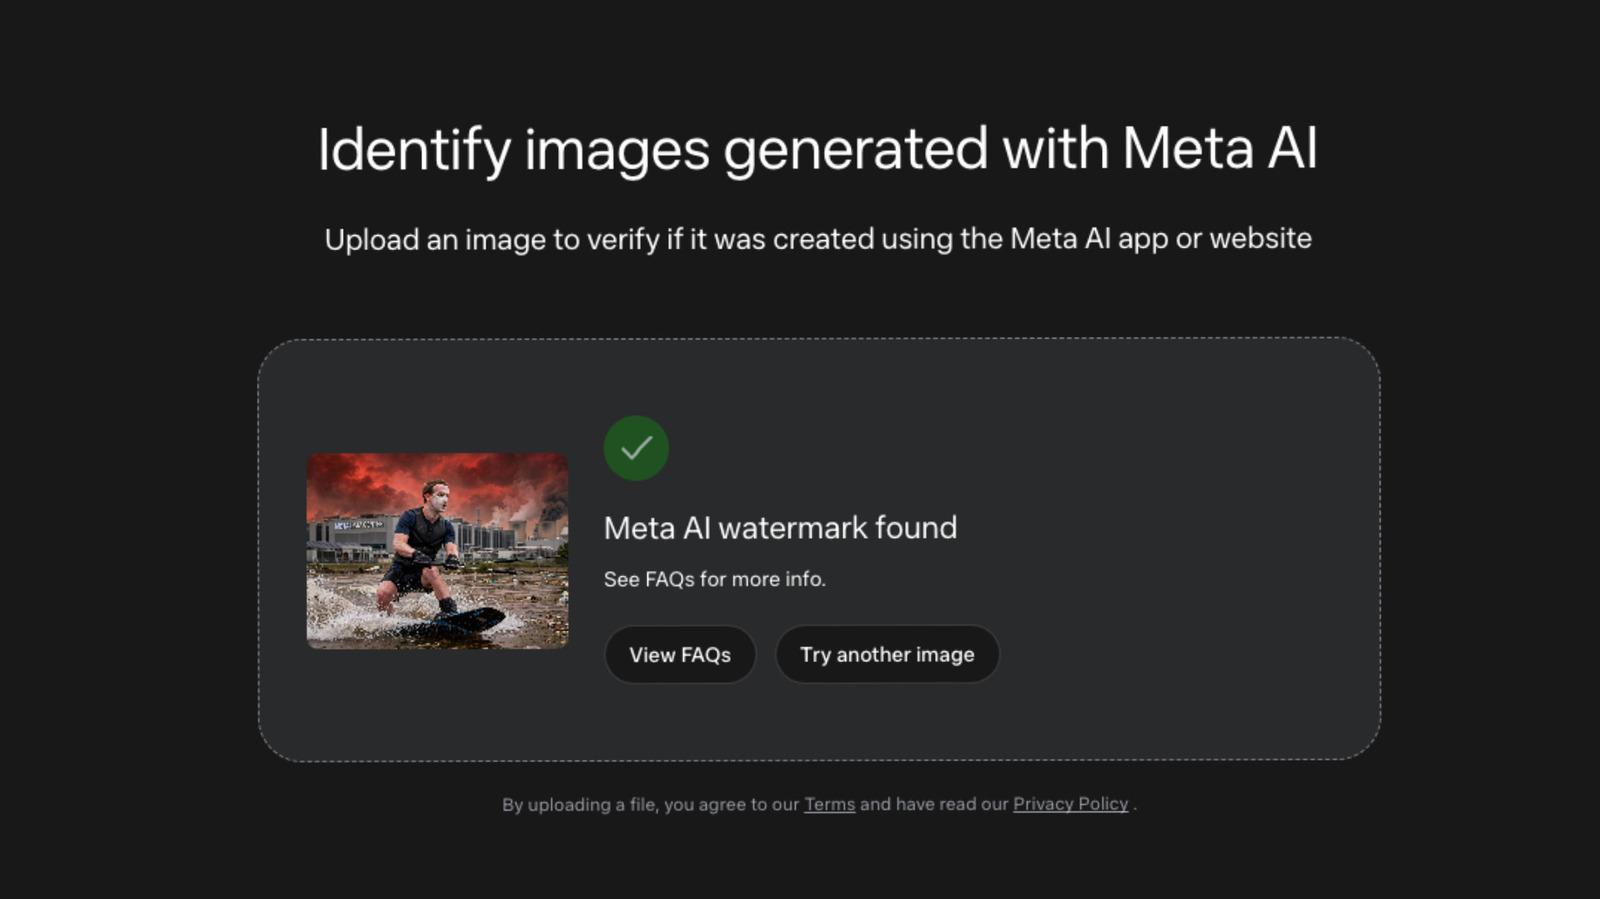
Meta has developed an AI detection tool aimed at identifying images and video produced by its own generative models. The move comes as pressure mounts on major AI developers to provide clearer signals about the origin of synthetic media, particularly ahead of high-stakes events like elections where misleading content can spread quickly.
The tool is designed to work specifically with output from Meta's own image and video generation systems, meaning it is not a general-purpose detector capable of flagging content from third-party models. That narrower scope is fairly common in this space - companies tend to have the best insight into the specific artifacts and patterns their own models leave behind, making model-specific detection more reliable than cross-model approaches.
One notable and somewhat puzzling aspect of the tool is that it enforces rate limits on usage. For a detection tool meant to help users or researchers verify whether content is AI-generated, rate limiting could slow down the kind of high-volume screening that journalists, platforms, or fact-checkers might need to do. Meta has not offered a detailed public explanation for why these limits exist, though they could relate to server costs, abuse prevention, or plans for a tiered access model down the line.
The broader context here is that AI-generated image and video detection remains a difficult and unsolved problem. Watermarking and metadata-based approaches - like those backed by the C2PA standard - offer one path forward, while model fingerprinting and classifier-based detection offer another. Meta's tool appears to sit somewhere in that landscape, though without more technical disclosure it is hard to assess how robust it is to common post-processing steps like compression, cropping, or format conversion, which are known to degrade detection accuracy. As Meta continues to expand its generative AI offerings, the reliability and openness of tools like this will matter more over time.