gen‑ai.news

Archive, page 11

Every story we have published on generative image and video AI, newest first. 500 stories across 21 pages.

Looking for something specific? Search the archive · Browse by issue

[AINews] Fal’s H3 Max Live breaks the infinite videogen barrier
Video

[AINews] Fal’s H3 Max Live breaks the infinite videogen barrier

Fal's H3 Max Live model can generate video faster than real time, meaning output is produced more quickly than it would take to watch the finished clip. This crosses a threshold that has practical implications for interactive and live applications. It is early days, but the milestone signals a meaningful shift in what video generation pipelines can support.

Runway News | Introducing Solaris
Video

Runway News | Introducing Solaris

Runway has introduced Solaris, its first Interface World Model, which generates interactive user interfaces in real time, frame by frame, without requiring any code. The system represents a new direction for generative AI, moving beyond static images or video clips toward dynamic, responsive environments. It is an early look at how AI models might eventually power the interfaces people use to interact with software.

How Chime Used Runway to Produce Their Latest National TV Spot
Video

How Chime Used Runway to Produce Their Latest National TV Spot

Fintech company Chime worked with Runway to turn photographs of nearly 100 real customers into a finished national television advertisement. The production approach cut costs significantly - reportedly saving $200,000 on a single clip compared to traditional methods. The campaign offers a concrete look at how generative video tools are beginning to factor into professional broadcast workflows.

Video

Google AI Releases Gemini Omni 1.1 Flash: 40-Second Scene Extension, First/Last Frame Control, and 4K Upscaling

Google has updated its native multimodal video model with Gemini Omni 1.1 Flash, bringing a set of targeted improvements to scene extension, frame-level control, and output resolution. The update extends the model's ability to read prior video context from a single frame to a full 10-second window, enabling more coherent continuations. First and last frame pinning, along with 4K upscaling, round out the changes.

AI-generated videos are already displacing actors and livestreamers across China's entertainment industry
Video

AI-generated videos are already displacing actors and livestreamers across China's entertainment industry

China's short-drama industry has moved rapidly toward AI-generated content, with 95 percent of the 128,000 short dramas released in Q1 2026 produced using AI. Actors report being asked to surrender their voice and likeness data before losing their jobs, and labor disputes tied to AI displacement are climbing. The trend offers an early, concrete look at how generative video is reshaping entertainment workforces at scale.

LAION drops massive open video dataset with 10 million hours of footage for AI research
Video

LAION drops massive open video dataset with 10 million hours of footage for AI research

LAION has released its Big Video Dataset (BVD), a large open collection of 80 million videos totaling 10 million hours of footage, aimed at advancing AI video research. The dataset also includes 55 million automatically described clips, and models trained on it have outperformed those trained on the previous benchmark dataset, InternVid. Its open availability marks a notable moment for researchers who have lacked large-scale, freely accessible video data.

Edit Image Quality Update
Image

Edit Image Quality Update

Midjourney has pushed an update to its V8.2 edit model, addressing image quality issues some users encountered over the past day. The fix arrives quickly after reports surfaced, and the team is encouraging users to retry any edits that fell short. Further updates are said to be on the way.

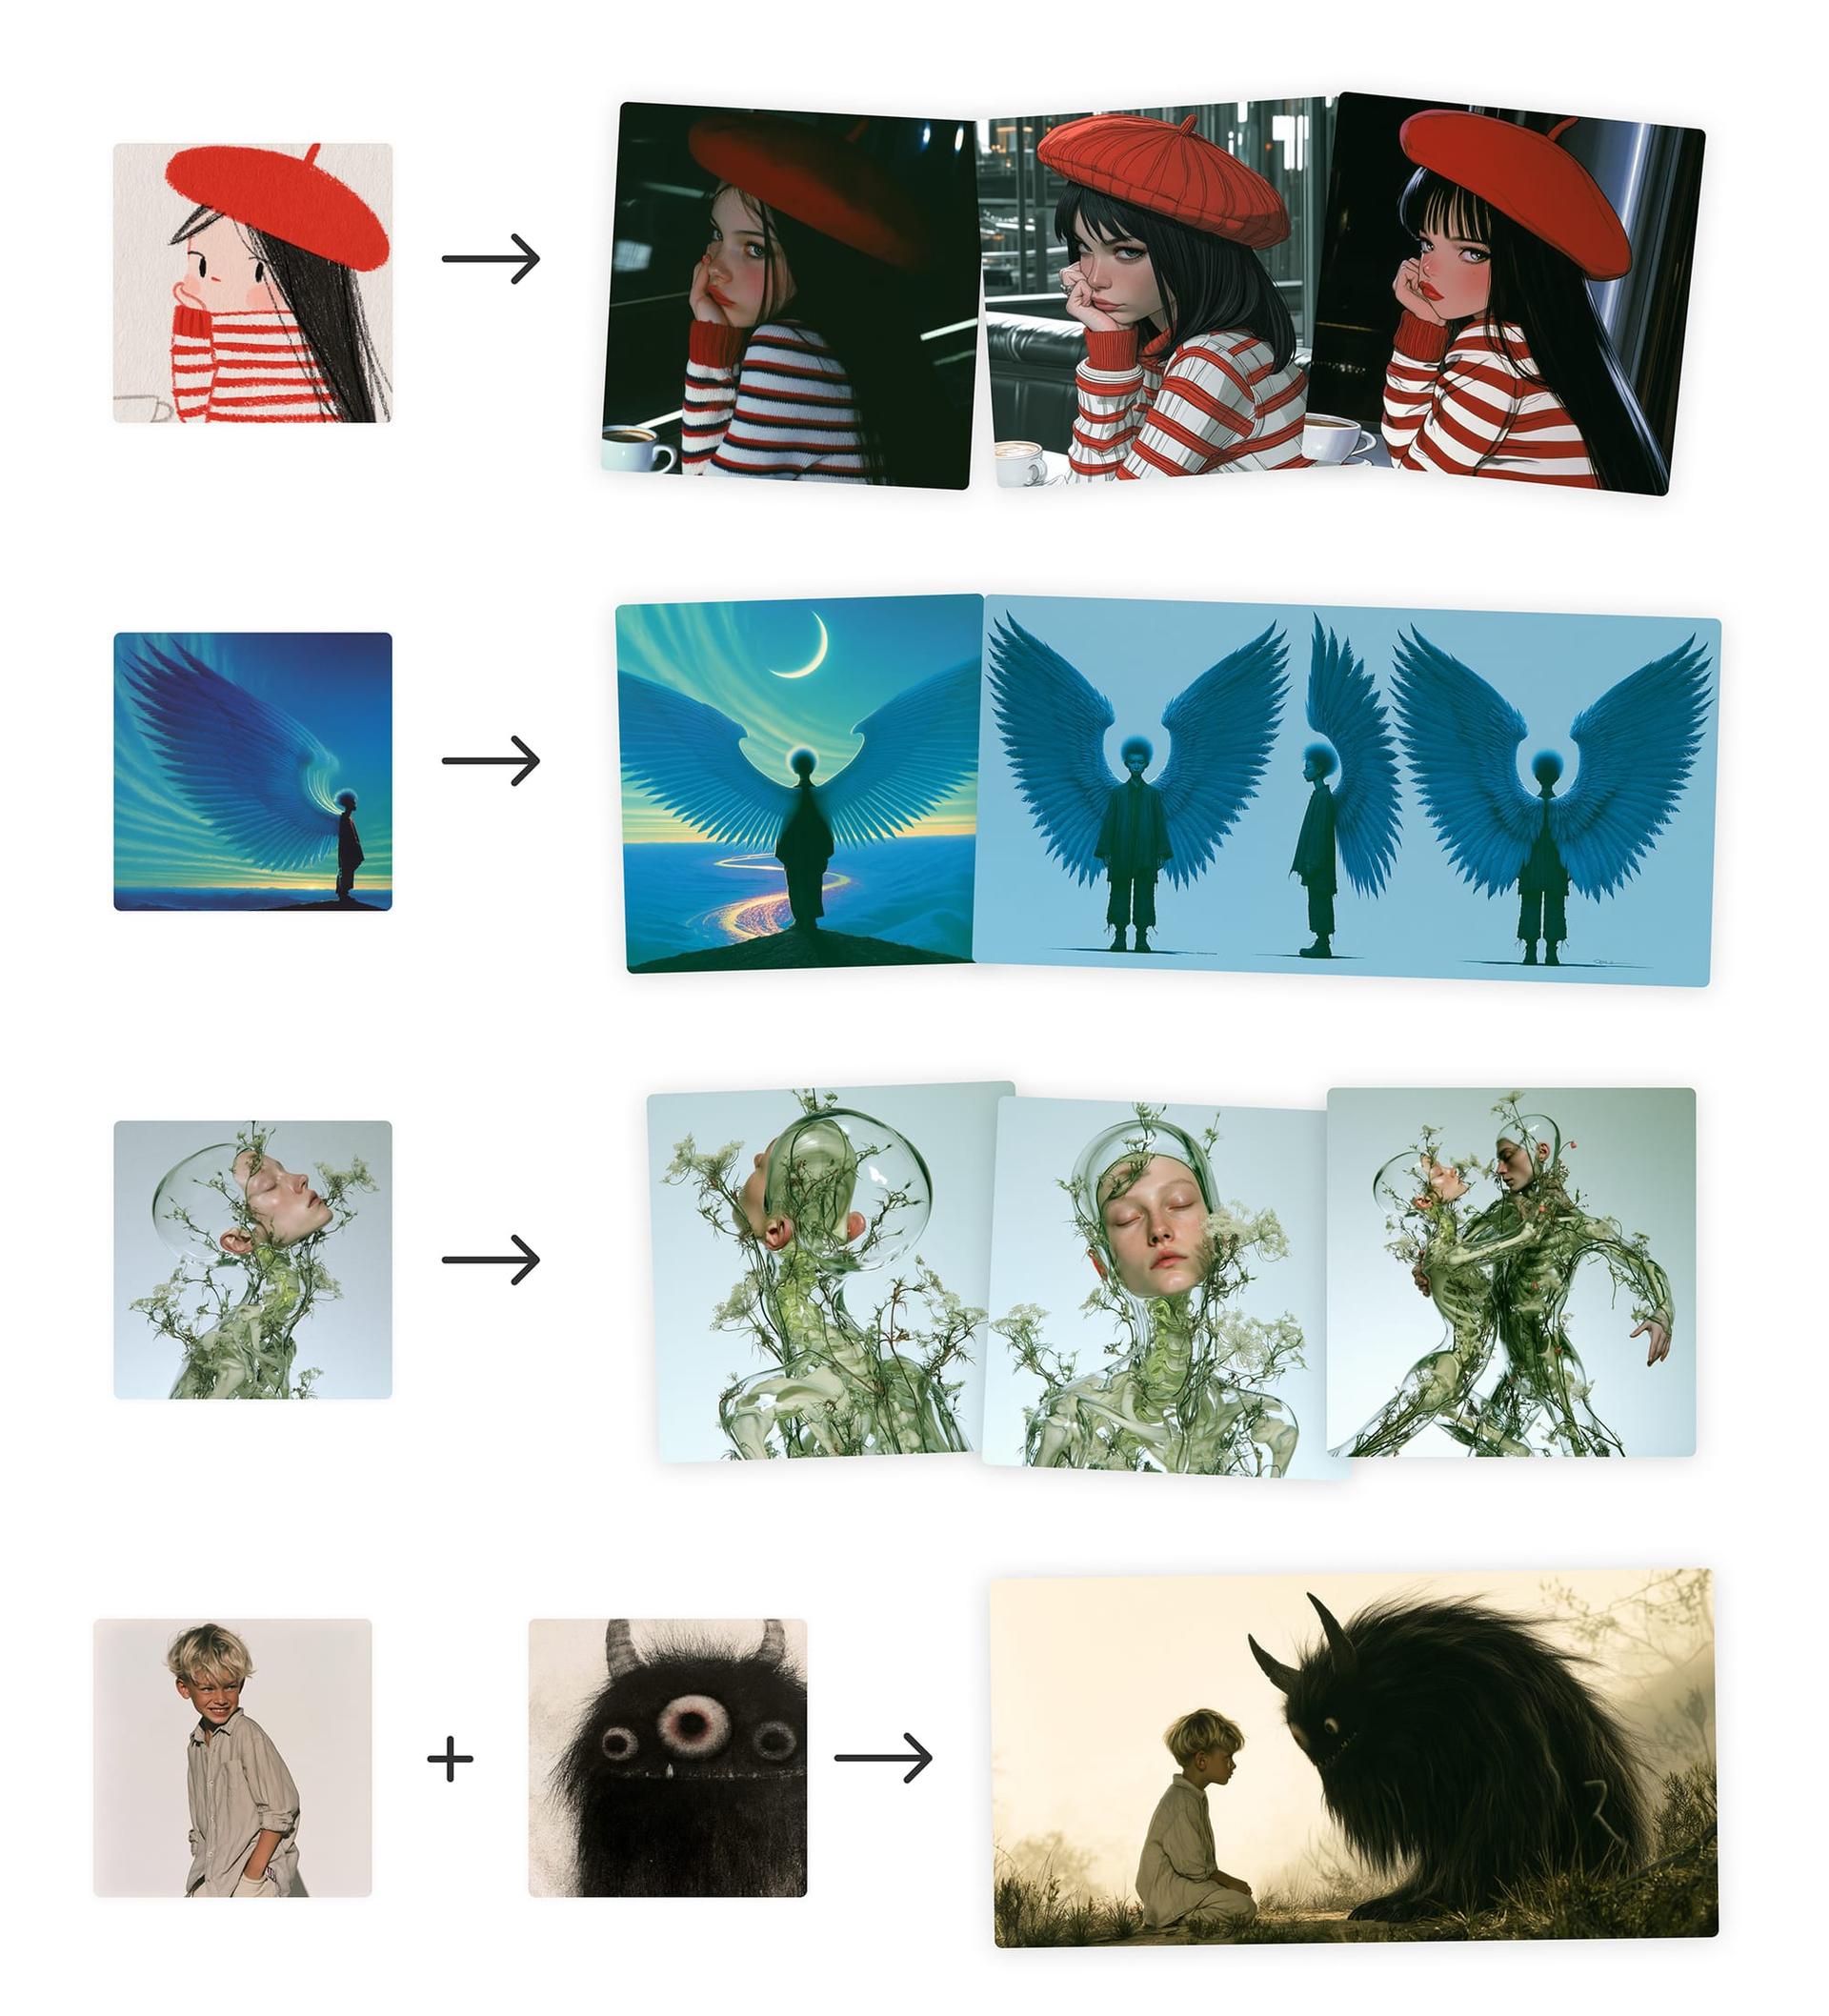
Edit Model for V8
Image

Edit Model for V8

Midjourney has begun rolling out an early test of its V8.2 edit model, bringing instruction-based editing, multi-image reference generation, and inpainting to its latest generation pipeline. The update replaces the previous omni-reference system and supports up to four image references at once. It marks a notable expansion of what users can do directly within the Midjourney platform without leaving to third-party tools.

Google's Gemini Omni 1.1 Flash makes AI video generation cheaper and more flexible
Video

Google's Gemini Omni 1.1 Flash makes AI video generation cheaper and more flexible

Google has updated its Gemini Omni 1.1 Flash video model with broader context analysis, longer scene extension limits, and a lower-cost draft mode. The changes address practical concerns around consistency and affordability in AI-generated video. For developers and creators working at scale, the update shifts the cost-quality tradeoff in a meaningful direction.

Google Flow brings new creative control features to enhance video editing.
Video

Google Flow brings new creative control features to enhance video editing.

Google is expanding its Flow video creation tool with a new set of creative control features, building on the Gemini 2.5 Flash model first introduced at Google I/O. The updates give filmmakers and creators more precise tools for shaping their video outputs. The rollout marks a continued push by Google to make AI-assisted video editing more practical for professional and creative workflows.

Gemini Omni 1.1 Flash lets you build with more control
Video

Gemini Omni 1.1 Flash lets you build with more control

Google has updated its Gemini Omni 1.1 Flash model with a new set of creative controls and generative video features aimed at developers. The release expands what builders can direct and fine-tune when generating video content through the API. It marks a continued push by Google to give developers more precise influence over model outputs.

Cocomelon's Studio Tells Its Artists to Start Experimenting With AI
Video

Cocomelon's Studio Tells Its Artists to Start Experimenting With AI

Moonbug Entertainment, the studio behind Cocomelon and Blippi, has instructed its artists to begin experimenting with AI tools as part of a broader shift in its production workflow. The company says human oversight will remain a core part of the process. The move raises questions about how AI adoption will affect the artists and animators who work on these widely watched children's properties.

Adobe is adding more AI to Photoshop
Image

Adobe is adding more AI to Photoshop

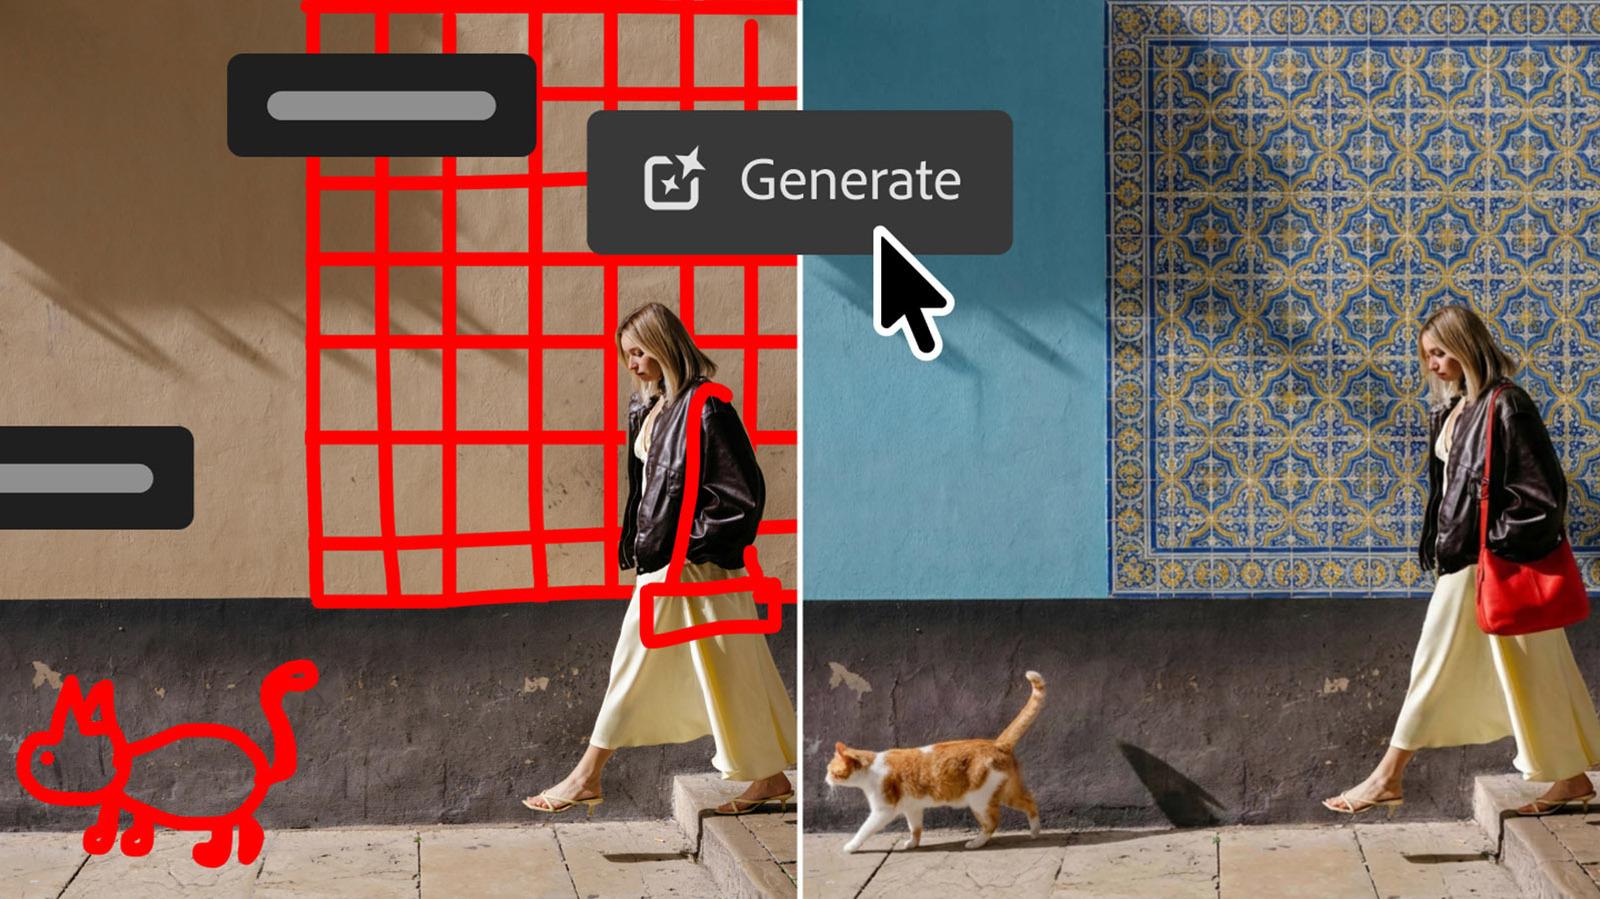
Adobe is updating Photoshop with a dedicated "AI Assisted Editor" view, currently in beta, that consolidates the app's AI tools into a single toolbar. The update also introduces a "markup" feature that lets users draw directly on an image to guide the AI on what to change - no text prompts required.

Photoshop's new 'Markup' feature lets you draw on images to show what you want
Image

Photoshop's new 'Markup' feature lets you draw on images to show what you want

Adobe Photoshop is adding a new "Markup" tool that lets users sketch directly on an image to guide AI-based generation - communicating intent visually rather than through text prompts alone. The update also brings Lightroom-style controls to Photoshop, a long-requested addition for photographers and retouchers who work across both apps.

Your Edit Isn’t Finished Until It Sounds Right
Video

Your Edit Isn’t Finished Until It Sounds Right

Adobe Firefly has expanded into audio with three tools - Generate Music, Generate Speech, and Generate Sound Effects - designed to bring sound into the editing process earlier than traditional workflows allow. Rather than treating audio as a final step after the picture is locked, creators can now use generated sound to test pacing and tone while a project is still taking shape. The tools are integrated into Firefly's broader multi-model creative environment alongside image and video generation.

Multimodal

Z.ai Releases GLM-5.3-Flash: A 320B-A18B Natively Multimodal MoE With a 1M-Token Context

Z.ai has released GLM-5.3-Flash, the first model in the GLM-5 series to handle multiple modalities natively, built on a Mixture-of-Experts architecture with 320 billion total parameters and 18 billion active at inference time. The model supports a context window of just over one million tokens and is available under an MIT license. API access is priced at $0.15 per million input tokens and $0.50 per million output tokens.

Stability AI, maker of image generator Stable Diffusion, raises $76 million in fresh funding
Image

Stability AI, maker of image generator Stable Diffusion, raises $76 million in fresh funding

Stability AI, the company behind the open-weight image generation model Stable Diffusion, has secured $76 million in new funding, bringing its total raised to $232 million. The round signals continued investor interest in open-source generative image infrastructure despite a competitive and crowded market. Details on the lead investor and use of funds have not yet been fully disclosed.

Introducing Runway Dev
Multimodal

Introducing Runway Dev

Runway has launched Runway Dev, an API platform giving developers programmatic access to its image, video, and character generation models. The offering is positioned as enterprise-ready from the start, consolidating multiple model capabilities under a single interface. It marks a deliberate move by Runway to expand beyond its consumer and creative-professional tools into the infrastructure layer of AI media production.

Apple Unveils Its New Mac Studio With M5 Max and M5 Ultra Options Aimed for On-Device AI
Multimodal

Apple Unveils Its New Mac Studio With M5 Max and M5 Ultra Options Aimed for On-Device AI

Apple has refreshed the Mac Studio with new M5 Max and M5 Ultra chip options, bringing meaningful spec bumps across CPU, GPU, storage, and memory bandwidth. While Apple's marketing leans heavily on AI performance figures, the underlying hardware gains are relevant for video editors and other creative professionals as well. The M5 Max starts at $2,499 and the M5 Ultra at $5,499.

How does converting a video to 4K actually work?
Video

How does converting a video to 4K actually work?

Upscaling a video to 4K is more nuanced than simply increasing a file's resolution setting. Modern software uses increasingly sophisticated techniques to fill in missing detail, but the results are not always perfect. Here is a look at how the process actually works and what limitations remain.

Alibaba's Wan3.0 generates AI videos up to 30 seconds long from text, images, and documents
Video

Alibaba's Wan3.0 generates AI videos up to 30 seconds long from text, images, and documents

Alibaba has released Wan3.0, a video generation model capable of producing clips up to 30 seconds long from a range of inputs including text prompts, images, PDFs, and PowerPoint files. A 30-second clip at 1080p is priced at $6. The release comes as Alibaba reported a sharp 75 percent year-over-year drop in quarterly profit, reflecting heavy investment in AI infrastructure.