gen‑ai.news

The pulse of generative image & video AI.

Twice a week, the most important stories in image and video generation - new models, notable research, and meaningful product releases - distilled into a 2-minute read. No hype, no filler.

Free. Unsubscribe any time. No spam, ever.

Archive

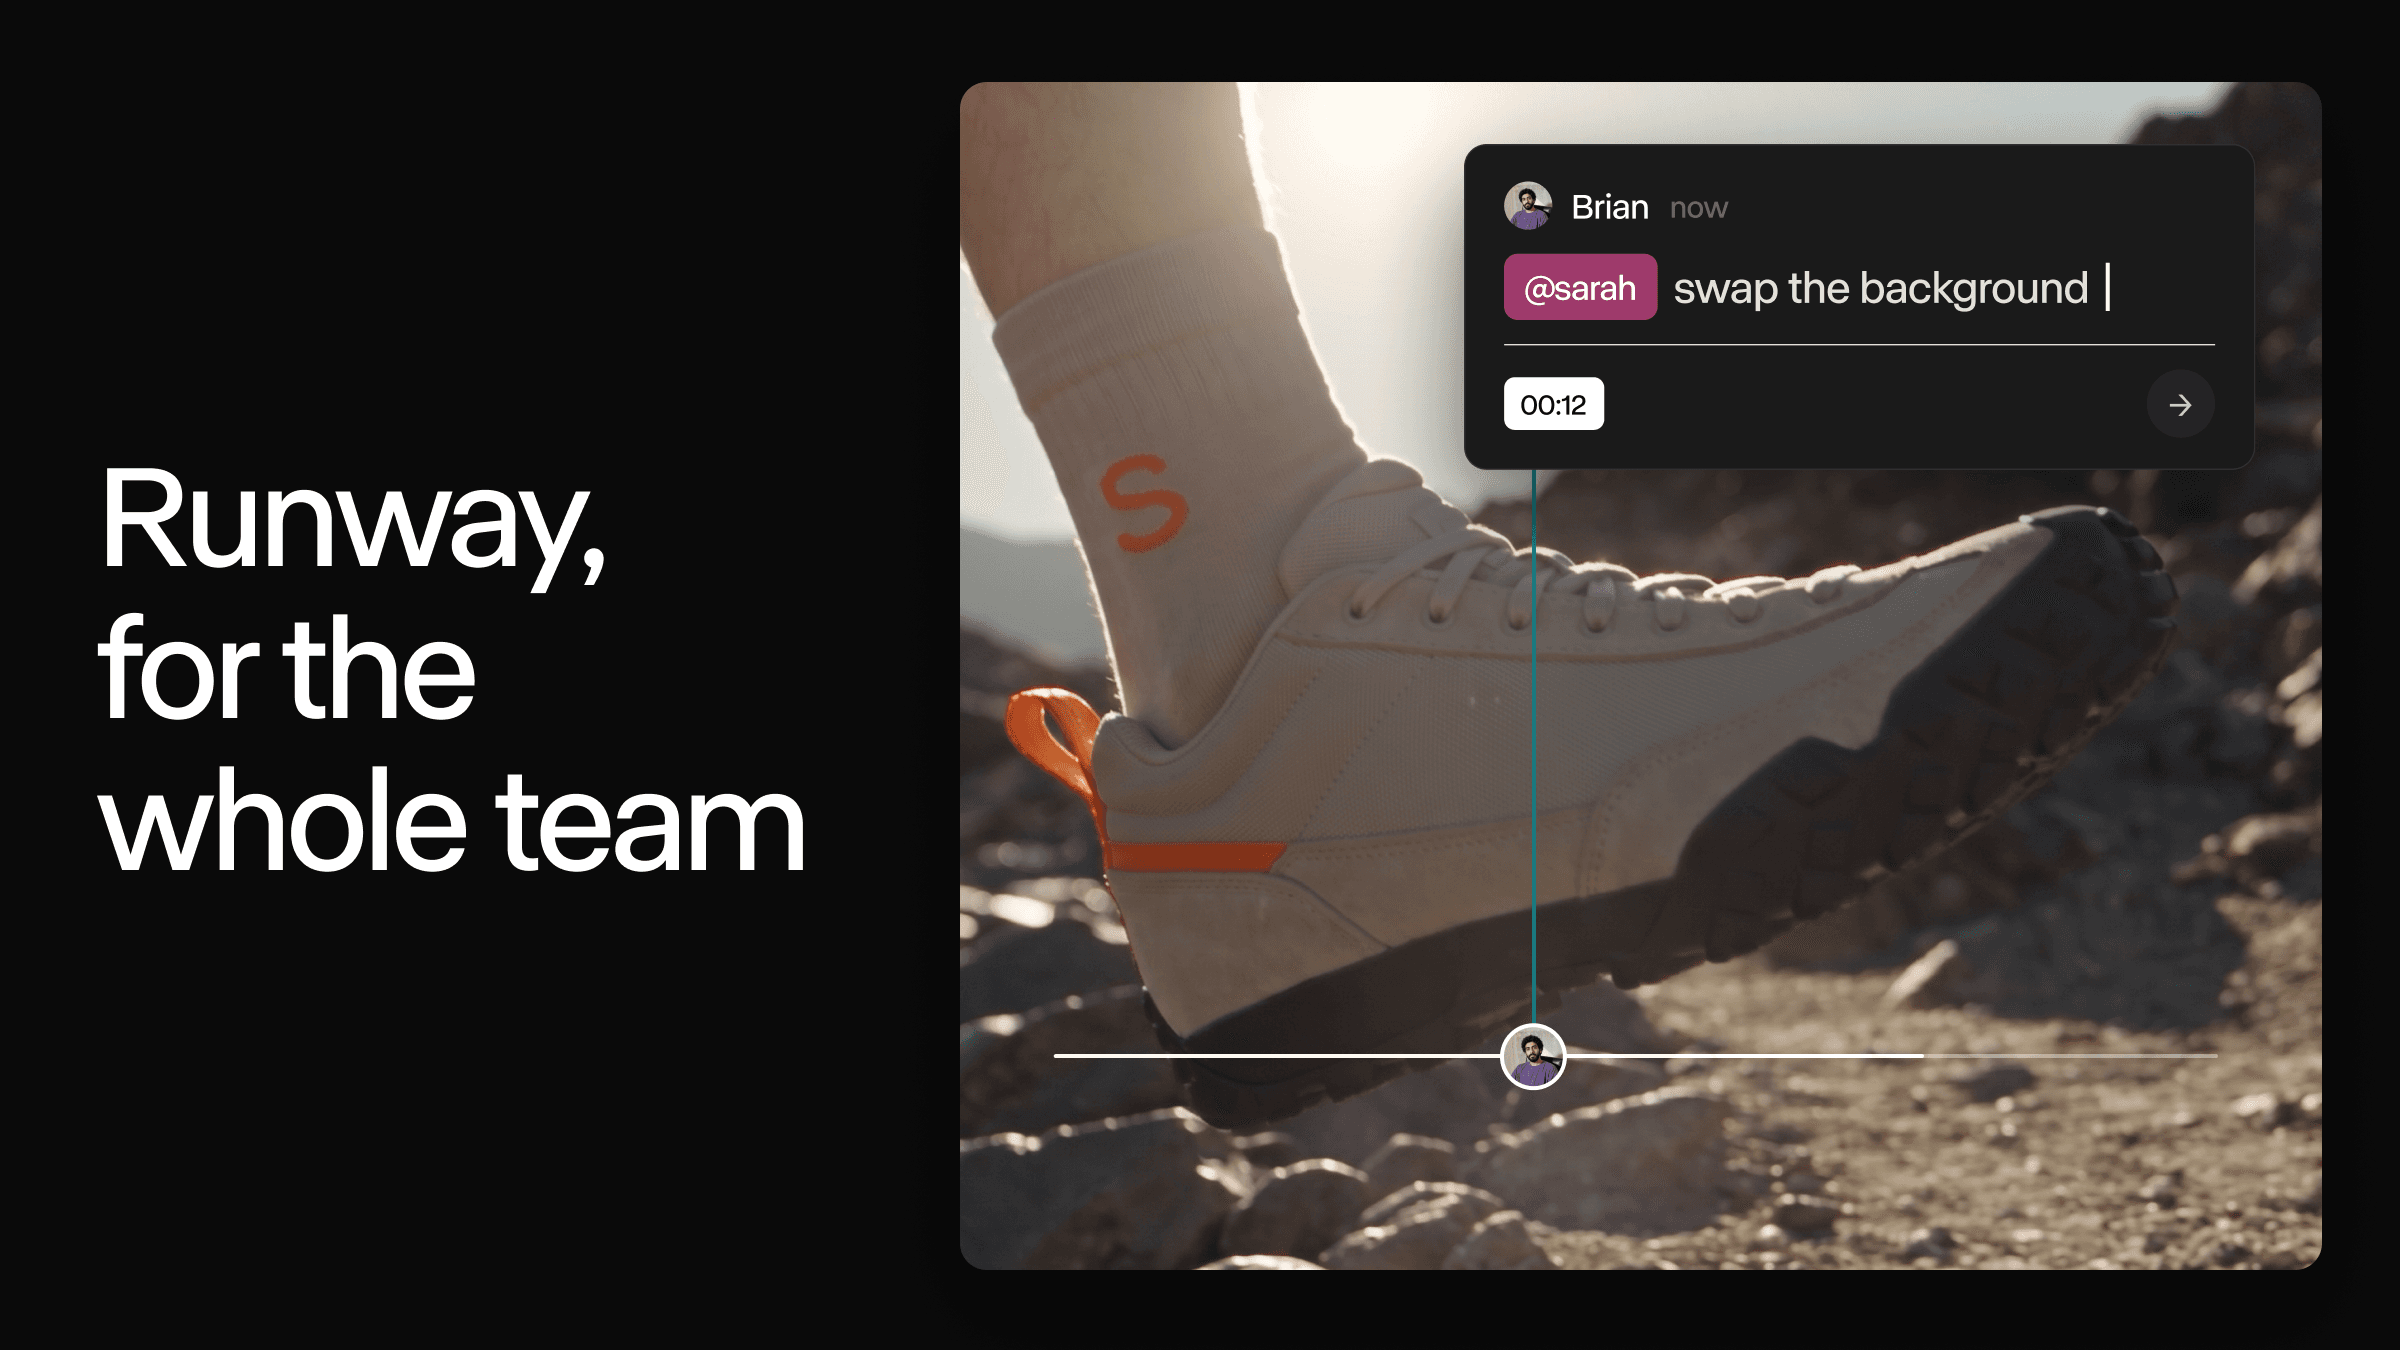
Runway News | Introducing Team Plan
Video

Runway News | Introducing Team Plan

Runway has launched a Team plan aimed at small creative groups, offering shared workspaces, pooled generation credits, and Brand Kits for two to nine seats at $55 per seat per month. The new tier sits between individual subscriptions and larger enterprise arrangements, making collaborative AI video work more practical for studios and agencies working at modest scale.

No image
Image

Google’s Gemini Spark can now manage your Google Photos library

Google has expanded Gemini Spark's capabilities to include direct management of Google Photos libraries, allowing the AI assistant to edit albums, create shared collections, and convert photos into calendar events. The feature is currently limited to AI Pro and Ultra subscribers. It marks a deeper integration between Google's AI assistant layer and its core photo storage product.

Instagram’s AI detection is a mess (again)
Image

Instagram’s AI detection is a mess (again)

Instagram's "AI Content" label, designed to flag synthetically generated images, has been misfiring in noticeable ways. Users report that the tag is appearing on photos edited with ordinary tools like Canva's background remover, while genuinely AI-generated imagery continues to go unlabeled. The inconsistency is undermining trust in the system rather than building it.

Why AI food looks like that
Image

Why AI food looks like that

Restaurants and food brands are increasingly using AI-generated images to promote their products, with results that range from odd to outright unsettling. Distorted noodles, lumpy burgers, and ice cream that looks more like brain matter are becoming a familiar sight. The underlying reasons come down to how diffusion models actually learn to represent food.

No image
Image

The sameness problem behind those unappetizing AI-generated menus

Restaurants are increasingly turning to generative AI to produce food imagery for their menus, but customers are picking up on something being off - even if they can't always articulate what. The homogenizing tendencies of AI image models mean that dishes end up looking idealized and interchangeable, stripping away the character that makes food photography feel honest. The gap between expectation and reality can leave diners disappointed before they've even ordered.

You Can Now Use Gemini Spark to Manage Your Google Photos
Image

You Can Now Use Gemini Spark to Manage Your Google Photos

Google has expanded Gemini Spark's capabilities to include direct integration with Google Photos, giving AI Pro and Ultra subscribers a way to manage their photo libraries through natural language prompts. The update covers editing, organizing, and sharing photos without needing to navigate the app manually. It marks a notable step in bringing conversational AI into everyday personal media management.

No image
Image

Collecting ideas to improve Midjourney

Midjourney is asking its user community to submit ideas and feedback to help shape what the team works on next. A formal voting session is planned within the next week or two, giving users a direct say in the platform's development priorities.

Deeper Thinking More Accurate Generation Introducing Seedream 5 0 Lite
Image

Deeper Thinking More Accurate Generation Introducing Seedream 5 0 Lite

ByteDance has released Seedream 5.0 Lite, a lighter edition of its text-to-image model that incorporates deeper reasoning to improve generation accuracy. The update focuses on more precise prompt following and compositional fidelity without the full resource footprint of its larger counterpart. It represents a continued push by ByteDance's Seed team to make capable image generation more accessible and efficient.

Beyond Generation It Understands Design Introducing Seedream 5 0 Pro
Image

Beyond Generation It Understands Design Introducing Seedream 5 0 Pro

ByteDance's Seed team has introduced Seedream 5.0 Pro, a new image generation model that positions itself around design comprehension rather than pure visual output. The model aims to bridge the gap between generating images and understanding the underlying intent of design tasks. It represents an evolution in how the team is framing the role of generative models in creative and professional workflows.

Adobe brings 70+ tools from Photoshop, Illustrator and more to Slack
Image

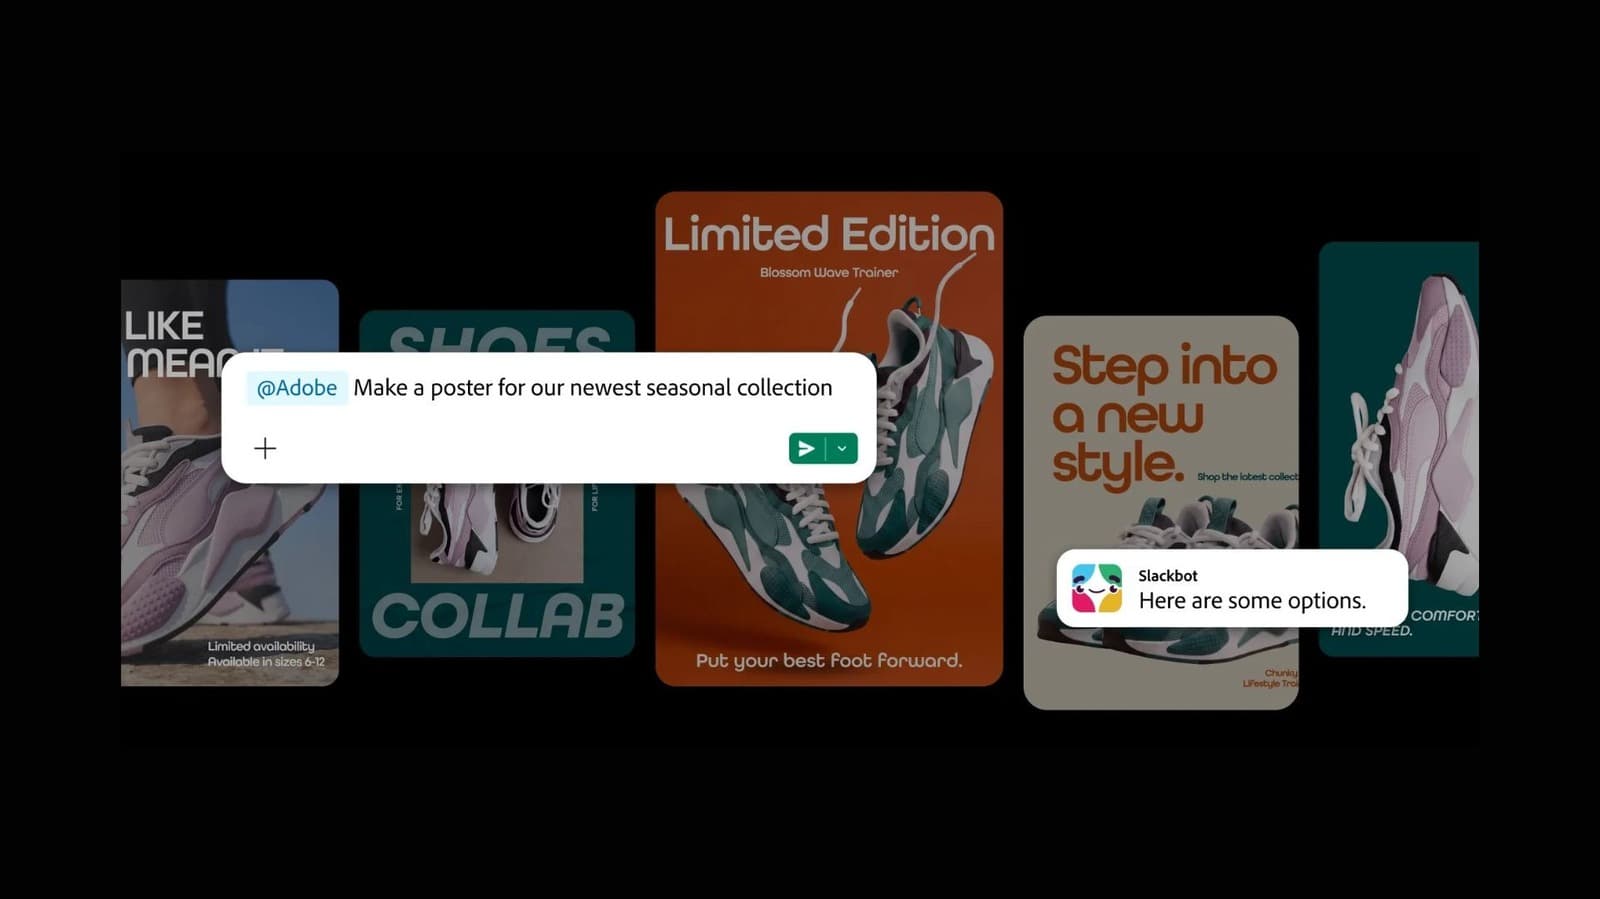
Adobe brings 70+ tools from Photoshop, Illustrator and more to Slack

Adobe has integrated more than 70 tools from its creative suite - including Photoshop, Illustrator, and Premiere Pro - directly into Slack. The integration lets users invoke creative actions through Slackbot without leaving their workflow. It marks a notable step toward embedding professional creative tooling into everyday collaboration software.

Eddie AI Launches an Agent Marketplace of Editing Agents Built on Great Filmmakers
Video

Eddie AI Launches an Agent Marketplace of Editing Agents Built on Great Filmmakers

Eddie AI has unveiled an Agent Marketplace featuring editing agents modeled on the body of work of notable filmmakers and editors, including Walter Murch, Thelma Schoonmaker, Roger Deakins, and more than two dozen others. Users can also build their own custom agents to enforce brand guidelines, legal checklists, or personal editing rules. The initial rollout includes 29 agents available through the Eddie AI platform.

No image
Image

We’re ‘dangerously close’ to dead internet theory, says Pangram’s CEO

AI-generated content is no longer confined to social media feeds - it's turning up in job applications, product reviews, and insurance claims, raising serious questions about authenticity online. Pangram Labs CEO argues we are approaching a tipping point where the web's foundational trust is at risk. A wave of startups is now working to build detection tools capable of separating human-created content from machine-generated output.

Caira Is the First Mirrorless Camera System With Built-In AI Video Editing
Video

Caira Is the First Mirrorless Camera System With Built-In AI Video Editing

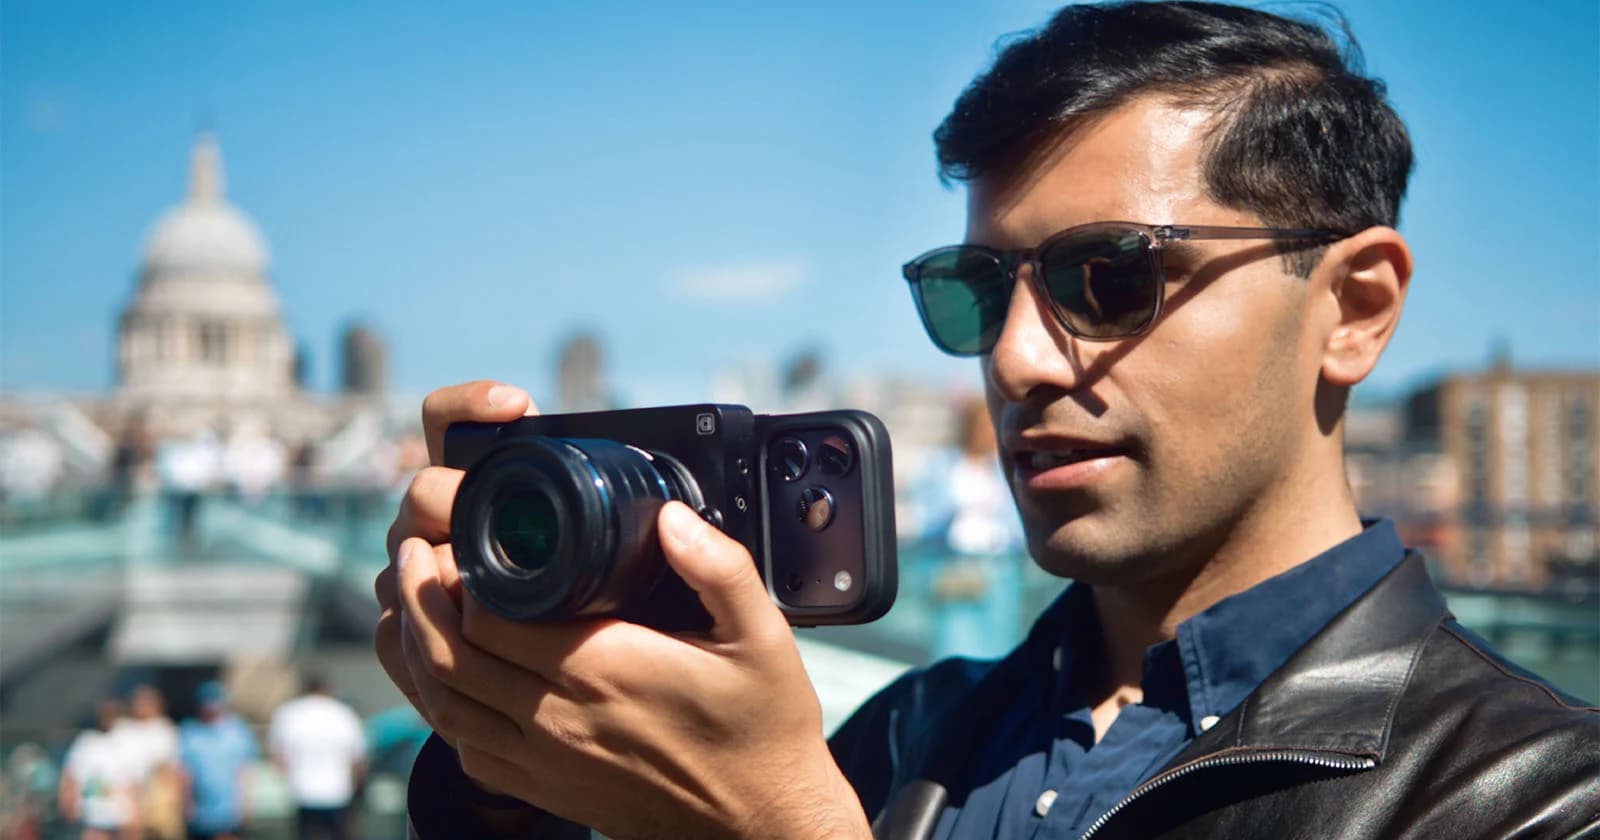
Camera Intelligence has introduced Caira, a Micro Four Thirds mirrorless camera that incorporates generative video editing directly into the hardware. It is the first mirrorless system to bring this kind of AI-native capability on-board, removing the need for post-production software to apply generative edits. The camera positions itself as an end-to-end production tool for videographers.

Introducing Runway Dev MCP
Multimodal

Introducing Runway Dev MCP

Runway has launched Runway Dev MCP, a hosted Model Context Protocol server designed to integrate Runway's AI capabilities directly into developer workflows. It allows coding agents to research models, configure routing, and troubleshoot failed generations without switching out of the editor environment.

The Republican Nominee for New York Governor Made a Creepy, AI-Generated Video of Mamdani and Hochul
Video

The Republican Nominee for New York Governor Made a Creepy, AI-Generated Video of Mamdani and Hochul

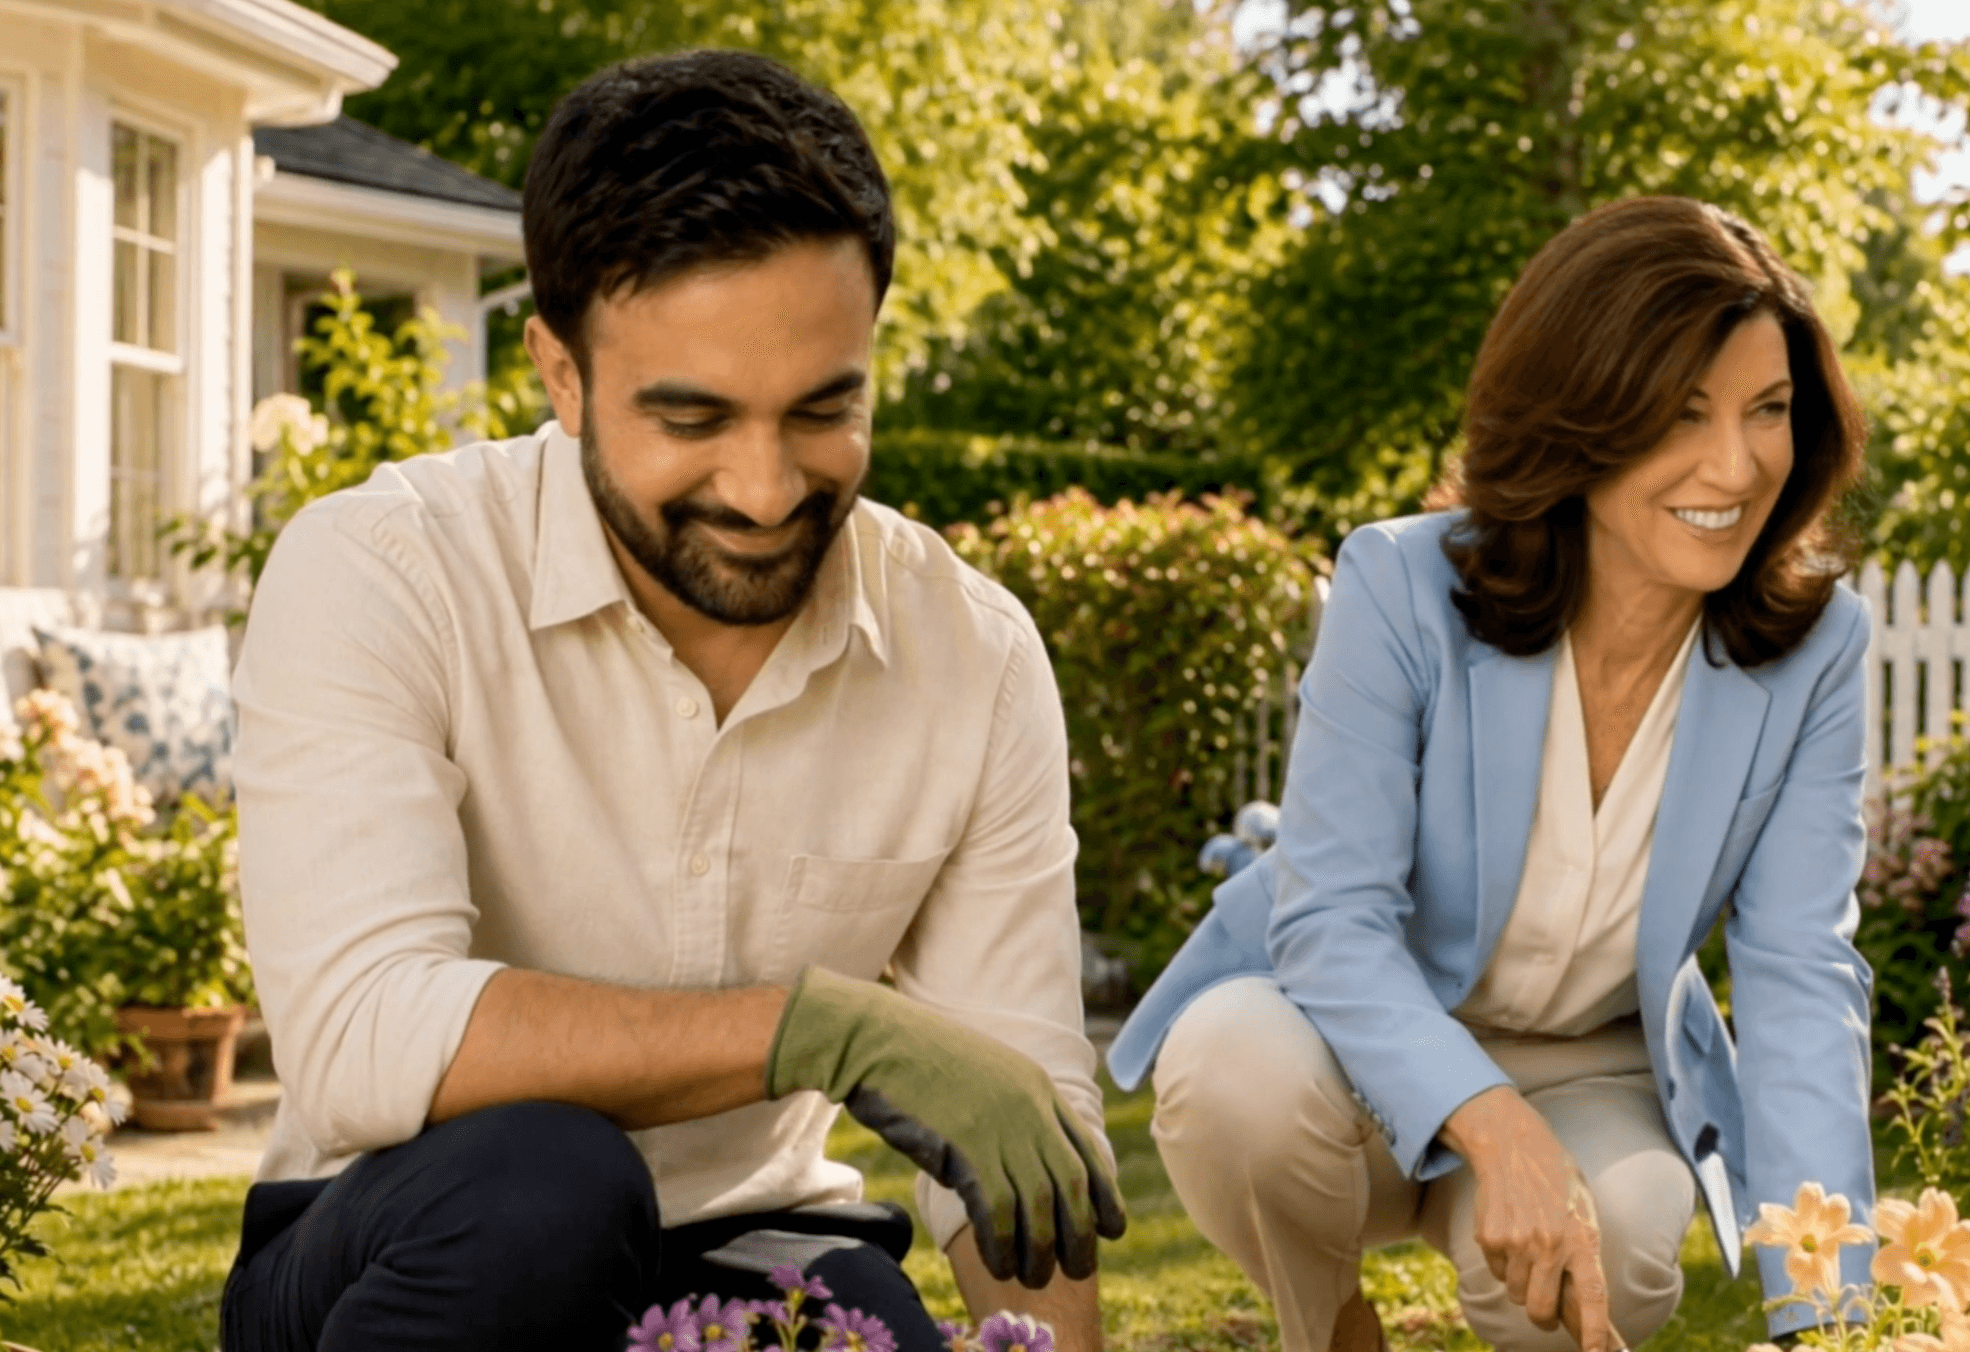
The Republican nominee for New York governor has released an AI-generated campaign video depicting Democratic figures Zohran Mamdani and Kathy Hochul in a way that critics are calling unsettling. The clip reportedly mimics the soft, warm aesthetic of a prescription drug advertisement. It is one of the more notable recent examples of AI-generated imagery entering state-level political advertising.

World Labs unveils Atlas, a single AI model that generates, reconstructs, and simulates 3D worlds from just a few photos
Multimodal

World Labs unveils Atlas, a single AI model that generates, reconstructs, and simulates 3D worlds from just a few photos

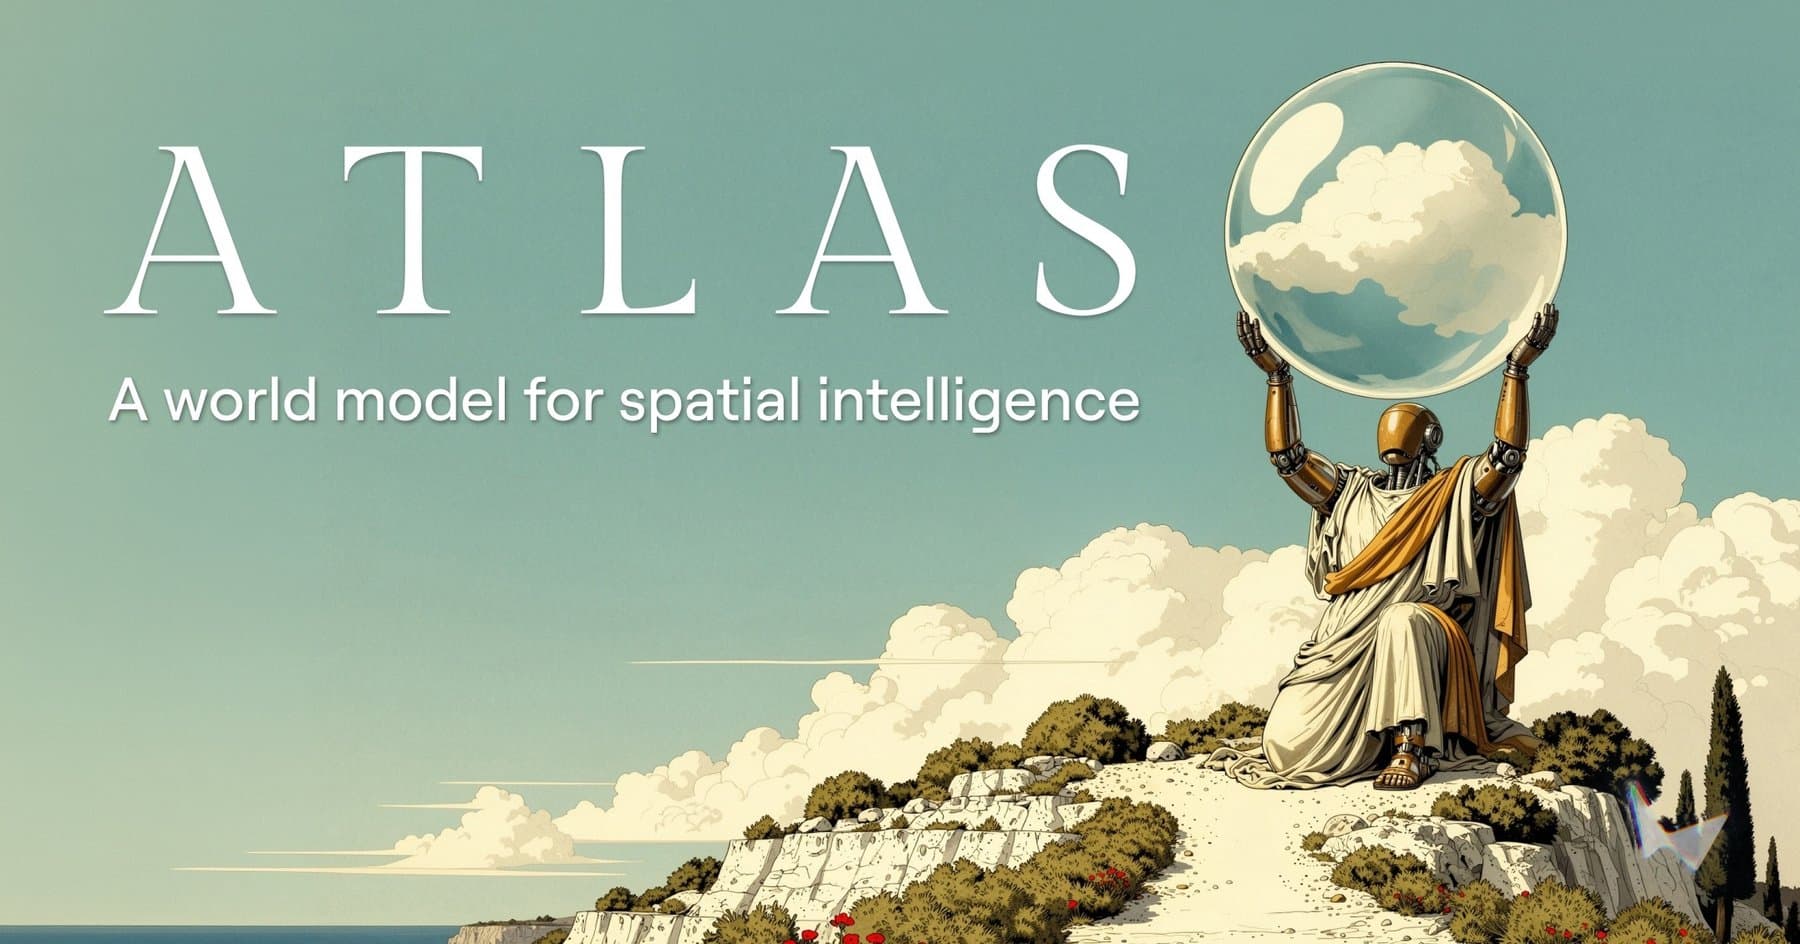
World Labs has introduced Atlas, a single AI model capable of generating, reconstructing, and simulating 3D scenes from only a handful of input images. Unlike specialist models that treat inputs as flat sequences, Atlas anchors everything in 3D space from the start. The company also highlights its potential for producing synthetic training data for robotics.

One Take Creation Flexible Referencing Introducing Seedance 2 5
Video

One Take Creation Flexible Referencing Introducing Seedance 2 5

ByteDance's Seed team has unveiled Seedance 2.5, a video generation model focused on one-take creation and flexible referencing capabilities. The update aims to give creators more control over how source material - such as characters, styles, or objects - is carried through generated video. It represents a continued push by ByteDance to mature its generative video offerings for practical production use.

Google Gemini's new agent-based video analysis cuts token usage by up to 88 percent
Video

Google Gemini's new agent-based video analysis cuts token usage by up to 88 percent

Google is rolling out agent-based video analysis across several Gemini Flash models, letting the model choose which parts of a video to examine rather than processing every frame at a fixed rate. The approach cuts token consumption by up to 88 percent while reportedly improving accuracy, particularly on longer recordings. It marks a meaningful shift in how multimodal models handle video input at scale.
Google needs Hollywood more than the studios need AI
Video

Google needs Hollywood more than the studios need AI

Google has been quietly approaching major Hollywood studios about licensing deals that would let it train AI models on copyrighted film and television content, offering substantial payments in return. While the arrangement looks straightforward on paper, the risks and rewards are not evenly distributed between the two sides. The studios may have more to lose from these agreements than the upfront cash suggests.

Google Rolls Out Agentic Video Understanding Across Gemini Models
Video

Google Rolls Out Agentic Video Understanding Across Gemini Models

Google has added agentic video understanding to its latest Gemini models, enabling more accurate, multi-step reasoning over video content at lower token cost. The capability allows Gemini to handle longer, more complex video tasks autonomously rather than requiring repeated user prompting. Google says the update also reduces overall token usage.

How Miro Produced Its Keynote Video for Four Global Markets with Runway
Video

How Miro Produced Its Keynote Video for Four Global Markets with Runway

Miro's brand team used Runway to produce the keynote intro video for its Canvas26 event, localizing the content across four global markets without any live-action shooting or stock footage. The project cut production time roughly in half compared to traditional methods. It offers a concrete look at how an in-house creative team is integrating generative video into a real production workflow.

No image
Image

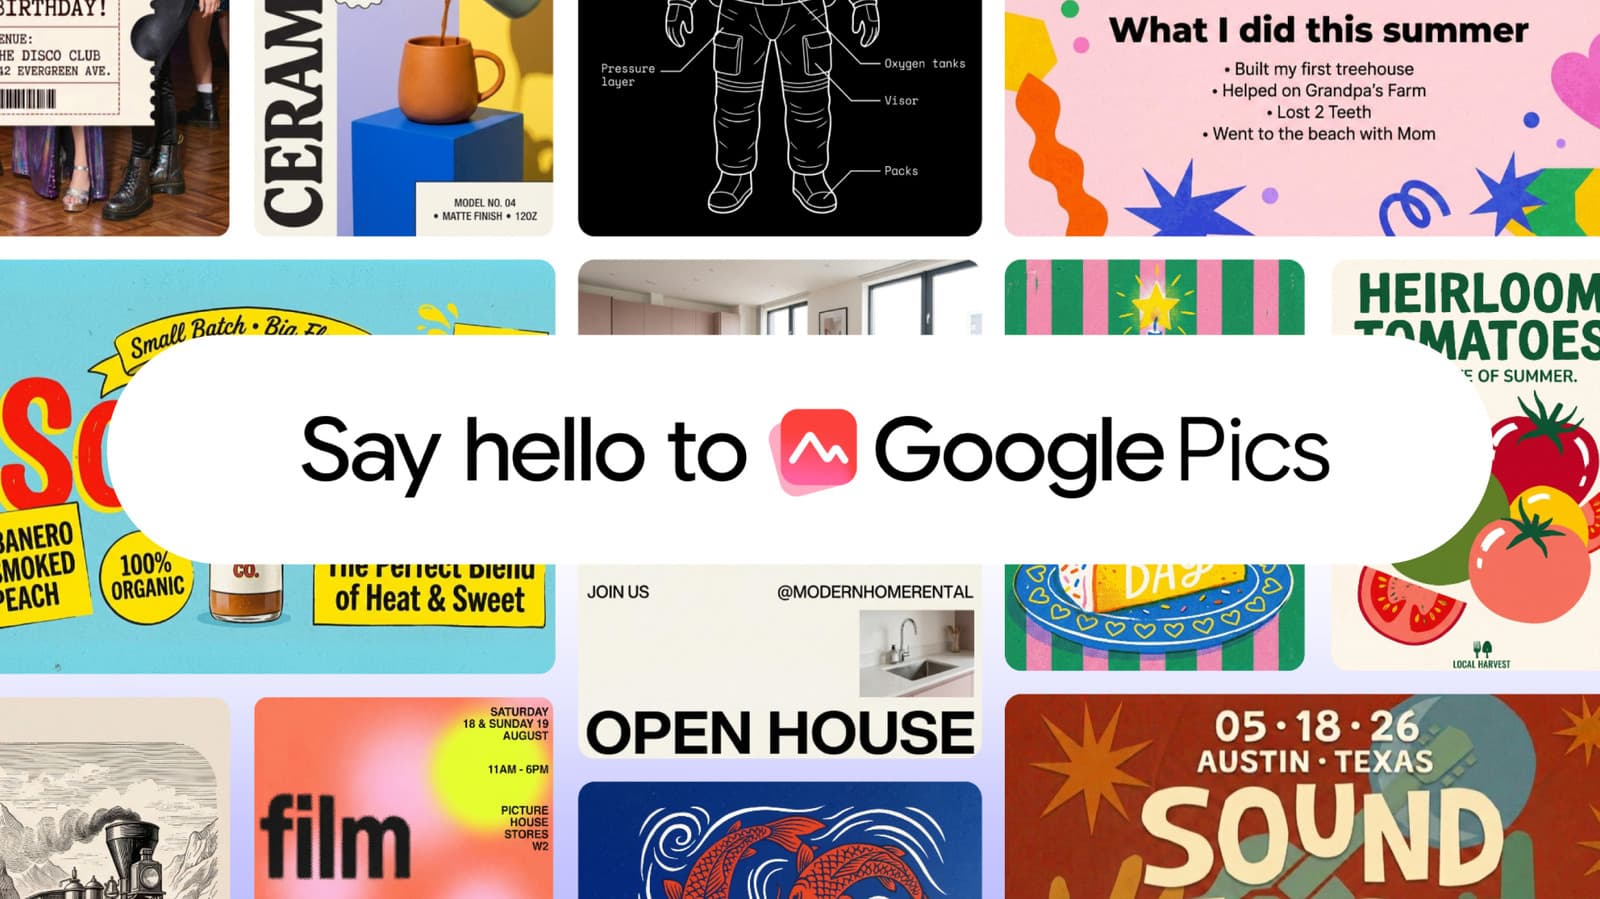
Google’s answer to Canva is an AI tool where you prompt instead of design

Google has introduced Google Pics, a prompt-driven design tool that positions itself as an AI-first alternative to platforms like Canva and Adobe. Rather than working with templates and drag-and-drop elements, users describe what they want and let the AI handle the visual composition. The move signals Google's intent to carve out space in the consumer and professional creative software market.

No image
Video

Introducing agentic video understanding with Gemini

Google DeepMind has introduced agentic video understanding capabilities within Gemini, allowing the model to actively analyze and reason over video content rather than passively responding to prompts. The update positions Gemini as a more autonomous tool for extracting meaning from visual and temporal information in video. This marks a step toward AI systems that can take initiative when working with complex, time-based media.

Visko launches Orbis, a new real-time AI video model
Video

Visko launches Orbis, a new real-time AI video model

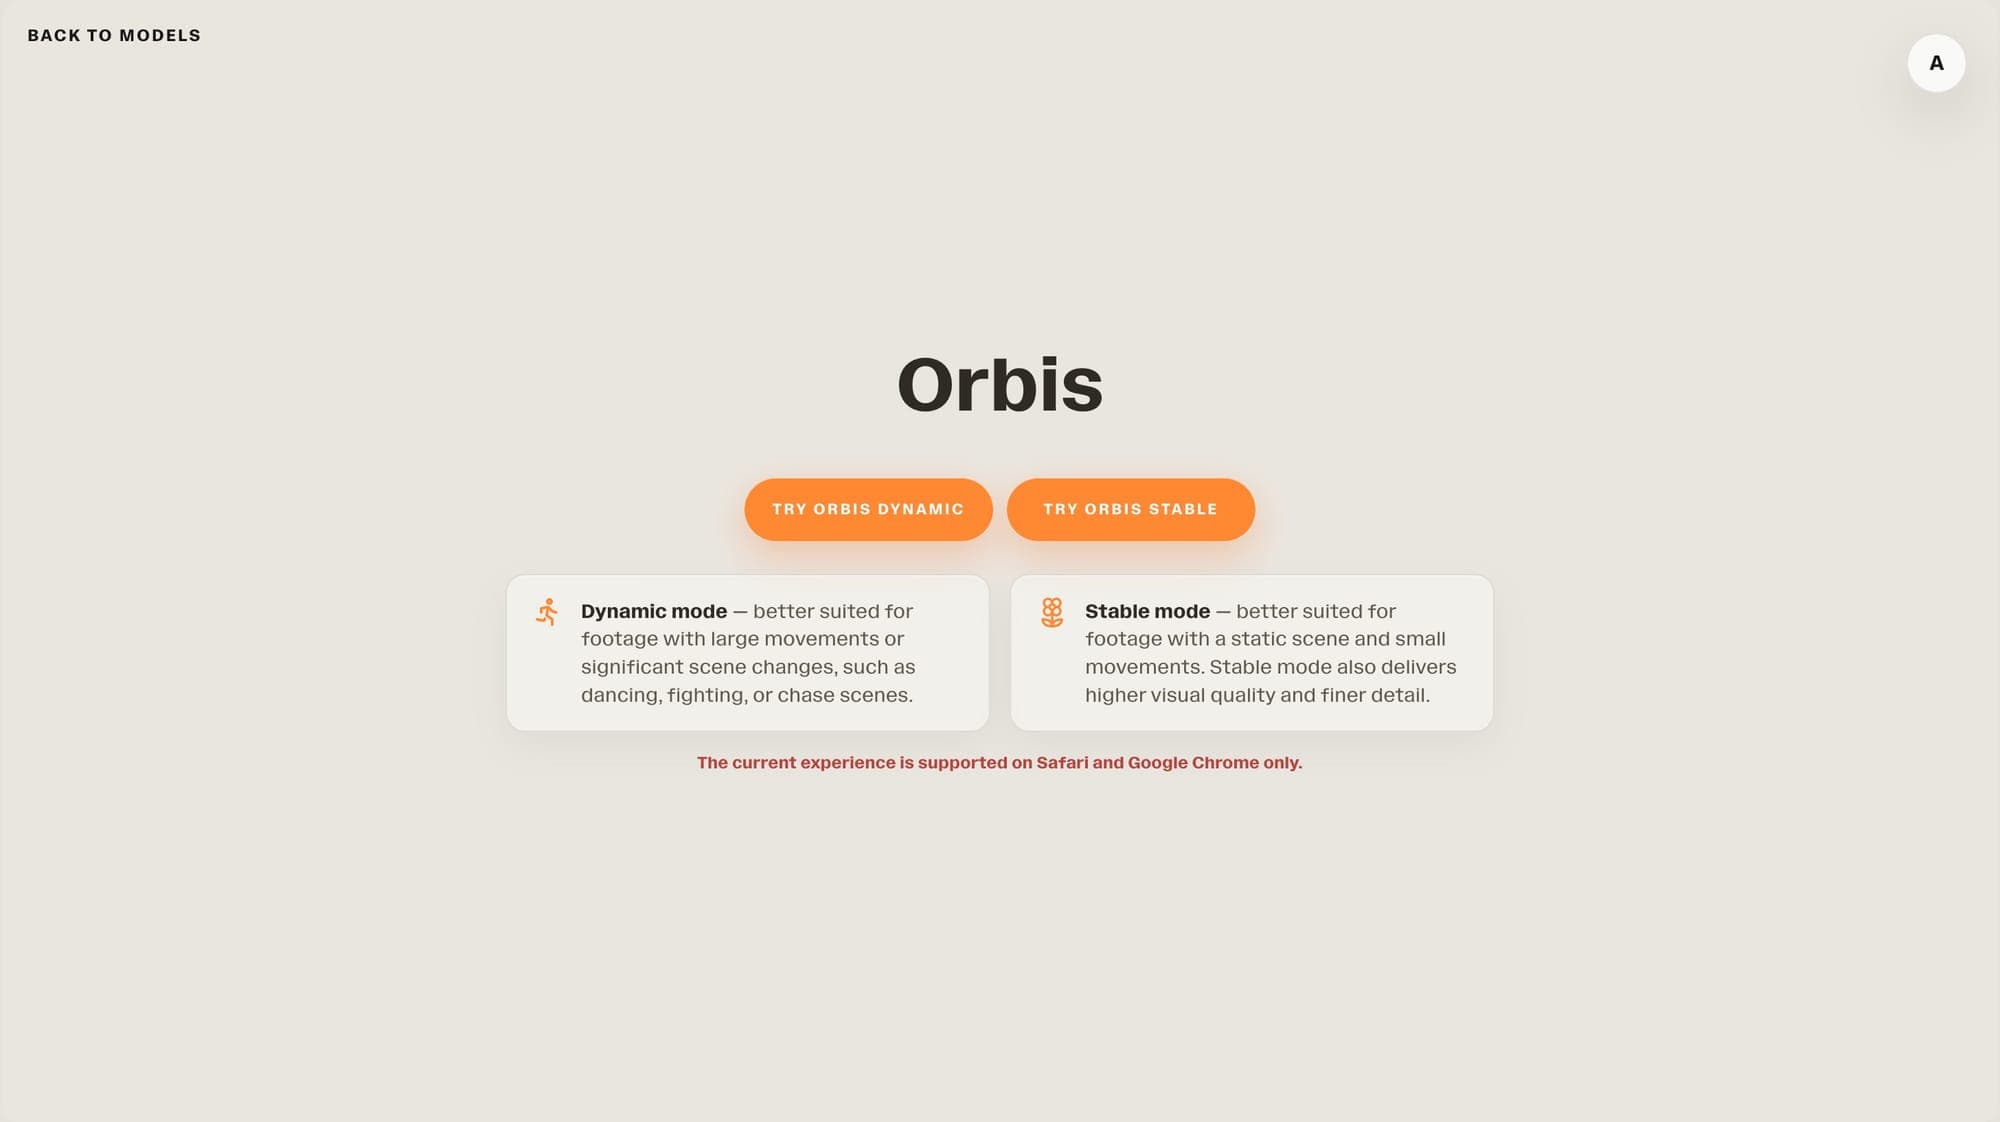
Visko has introduced Orbis, a video generation model capable of producing 4K output in real time. Unlike most generative video tools that render clips in full before delivering them, Orbis accepts prompt changes while the stream is still running. The combination of high resolution and live interactivity marks a notable step in how AI video generation can be used in practice.

Google Pics is like Canva, but with even more AI
Image

Google Pics is like Canva, but with even more AI

Google has introduced Pics, a suite of creative design tools built into Workspace that lets business users edit and generate images using AI. Built around Google's Gemini and the Nano Banana generative model, Pics offers more targeted control over image creation than typical chatbot interfaces. The tool is aimed at filling a gap where AI image generation has struggled to deliver consistent, usable results for professional and marketing contexts.

Google brings its Pics image editor to AI Pro and Ultra subscribers
Image

Google brings its Pics image editor to AI Pro and Ultra subscribers

Google is expanding access to its Pics image editor, making it available to subscribers of its AI Pro and Ultra plans. The move brings a dedicated AI-powered editing tool into Google's premium subscription tier, giving paying users another reason to stay within the Google ecosystem for creative work.

Try Google Pics: Easy image creation and editing in Google Workspace
Image

Try Google Pics: Easy image creation and editing in Google Workspace

Google has launched Pics, a new image creation and editing tool integrated into Google Workspace. Built on the company's latest Nano Banana model, the tool aims to make generating and modifying images straightforward for everyday users within the apps they already use. Here is what you need to know about the new offering.

DxO Releases PhotoLab 10 With AI Add-Ons, Masking, and Color Grading Updates
Image

DxO Releases PhotoLab 10 With AI Add-Ons, Masking, and Color Grading Updates

DxO has released PhotoLab 10, an update to its flagship photo-editing application that places a notable emphasis on AI-assisted masking and RAW image processing. The new version also brings color grading refinements aimed at tightening the overall editing workflow. Key additions address shortcomings from earlier releases while introducing new tools for more precise image control.

[AINews] Fal’s H3 Max Live breaks the infinite videogen barrier
Video

[AINews] Fal’s H3 Max Live breaks the infinite videogen barrier

Fal's H3 Max Live model can generate video faster than real time, meaning output is produced more quickly than it would take to watch the finished clip. This crosses a threshold that has practical implications for interactive and live applications. It is early days, but the milestone signals a meaningful shift in what video generation pipelines can support.

Runway News | Introducing Solaris
Video

Runway News | Introducing Solaris

Runway has introduced Solaris, its first Interface World Model, which generates interactive user interfaces in real time, frame by frame, without requiring any code. The system represents a new direction for generative AI, moving beyond static images or video clips toward dynamic, responsive environments. It is an early look at how AI models might eventually power the interfaces people use to interact with software.

How Chime Used Runway to Produce Their Latest National TV Spot
Video

How Chime Used Runway to Produce Their Latest National TV Spot

Fintech company Chime worked with Runway to turn photographs of nearly 100 real customers into a finished national television advertisement. The production approach cut costs significantly - reportedly saving $200,000 on a single clip compared to traditional methods. The campaign offers a concrete look at how generative video tools are beginning to factor into professional broadcast workflows.

No image
Video

Google AI Releases Gemini Omni 1.1 Flash: 40-Second Scene Extension, First/Last Frame Control, and 4K Upscaling

Google has updated its native multimodal video model with Gemini Omni 1.1 Flash, bringing a set of targeted improvements to scene extension, frame-level control, and output resolution. The update extends the model's ability to read prior video context from a single frame to a full 10-second window, enabling more coherent continuations. First and last frame pinning, along with 4K upscaling, round out the changes.

AI-generated videos are already displacing actors and livestreamers across China's entertainment industry
Video

AI-generated videos are already displacing actors and livestreamers across China's entertainment industry

China's short-drama industry has moved rapidly toward AI-generated content, with 95 percent of the 128,000 short dramas released in Q1 2026 produced using AI. Actors report being asked to surrender their voice and likeness data before losing their jobs, and labor disputes tied to AI displacement are climbing. The trend offers an early, concrete look at how generative video is reshaping entertainment workforces at scale.
LAION drops massive open video dataset with 10 million hours of footage for AI research
Video

LAION drops massive open video dataset with 10 million hours of footage for AI research

LAION has released its Big Video Dataset (BVD), a large open collection of 80 million videos totaling 10 million hours of footage, aimed at advancing AI video research. The dataset also includes 55 million automatically described clips, and models trained on it have outperformed those trained on the previous benchmark dataset, InternVid. Its open availability marks a notable moment for researchers who have lacked large-scale, freely accessible video data.

Edit Image Quality Update
Image

Edit Image Quality Update

Midjourney has pushed an update to its V8.2 edit model, addressing image quality issues some users encountered over the past day. The fix arrives quickly after reports surfaced, and the team is encouraging users to retry any edits that fell short. Further updates are said to be on the way.

Edit Model for V8
Image

Edit Model for V8

Midjourney has begun rolling out an early test of its V8.2 edit model, bringing instruction-based editing, multi-image reference generation, and inpainting to its latest generation pipeline. The update replaces the previous omni-reference system and supports up to four image references at once. It marks a notable expansion of what users can do directly within the Midjourney platform without leaving to third-party tools.
Google's Gemini Omni 1.1 Flash makes AI video generation cheaper and more flexible
Video

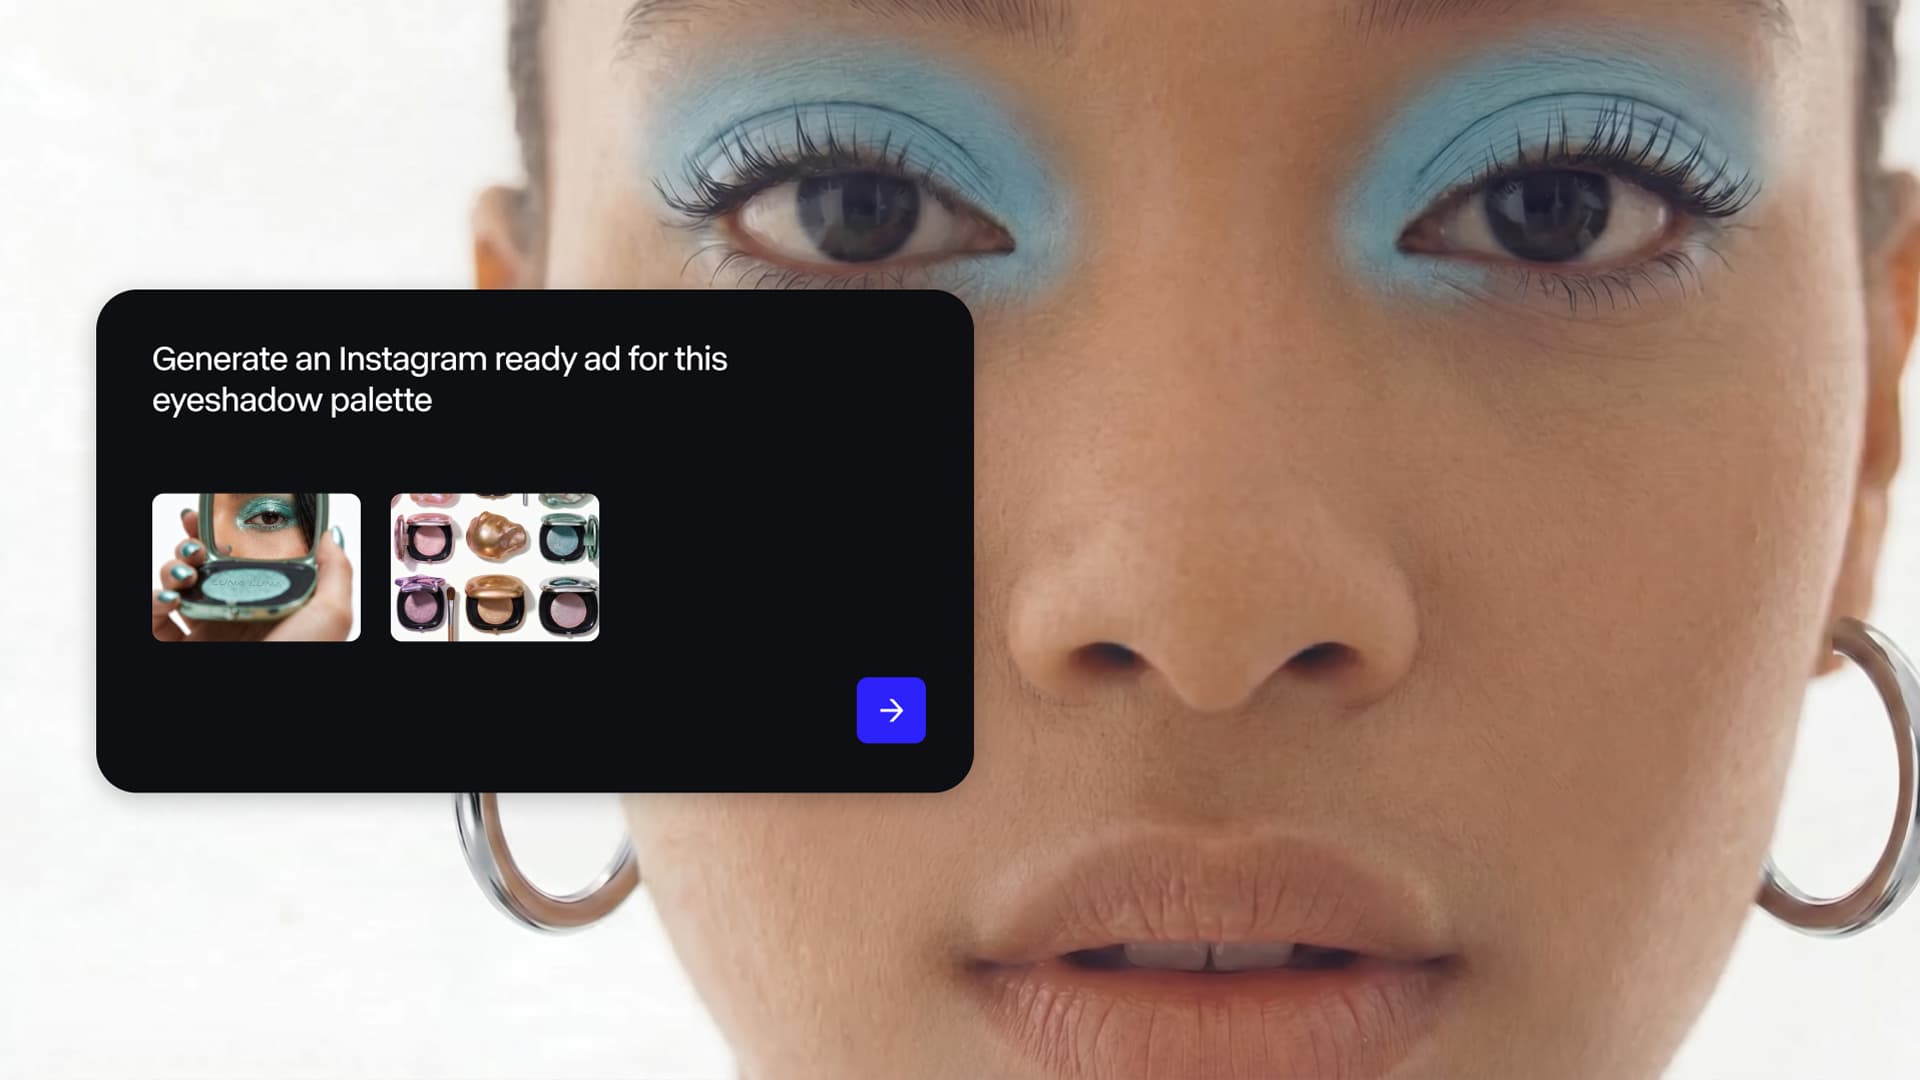
Google's Gemini Omni 1.1 Flash makes AI video generation cheaper and more flexible

Google has updated its Gemini Omni 1.1 Flash video model with broader context analysis, longer scene extension limits, and a lower-cost draft mode. The changes address practical concerns around consistency and affordability in AI-generated video. For developers and creators working at scale, the update shifts the cost-quality tradeoff in a meaningful direction.

Google Flow brings new creative control features to enhance video editing.
Video

Google Flow brings new creative control features to enhance video editing.

Google is expanding its Flow video creation tool with a new set of creative control features, building on the Gemini 2.5 Flash model first introduced at Google I/O. The updates give filmmakers and creators more precise tools for shaping their video outputs. The rollout marks a continued push by Google to make AI-assisted video editing more practical for professional and creative workflows.

Gemini Omni 1.1 Flash lets you build with more control
Video

Gemini Omni 1.1 Flash lets you build with more control

Google has updated its Gemini Omni 1.1 Flash model with a new set of creative controls and generative video features aimed at developers. The release expands what builders can direct and fine-tune when generating video content through the API. It marks a continued push by Google to give developers more precise influence over model outputs.

Cocomelon's Studio Tells Its Artists to Start Experimenting With AI
Video

Cocomelon's Studio Tells Its Artists to Start Experimenting With AI

Moonbug Entertainment, the studio behind Cocomelon and Blippi, has instructed its artists to begin experimenting with AI tools as part of a broader shift in its production workflow. The company says human oversight will remain a core part of the process. The move raises questions about how AI adoption will affect the artists and animators who work on these widely watched children's properties.

Adobe is adding more AI to Photoshop
Image

Adobe is adding more AI to Photoshop

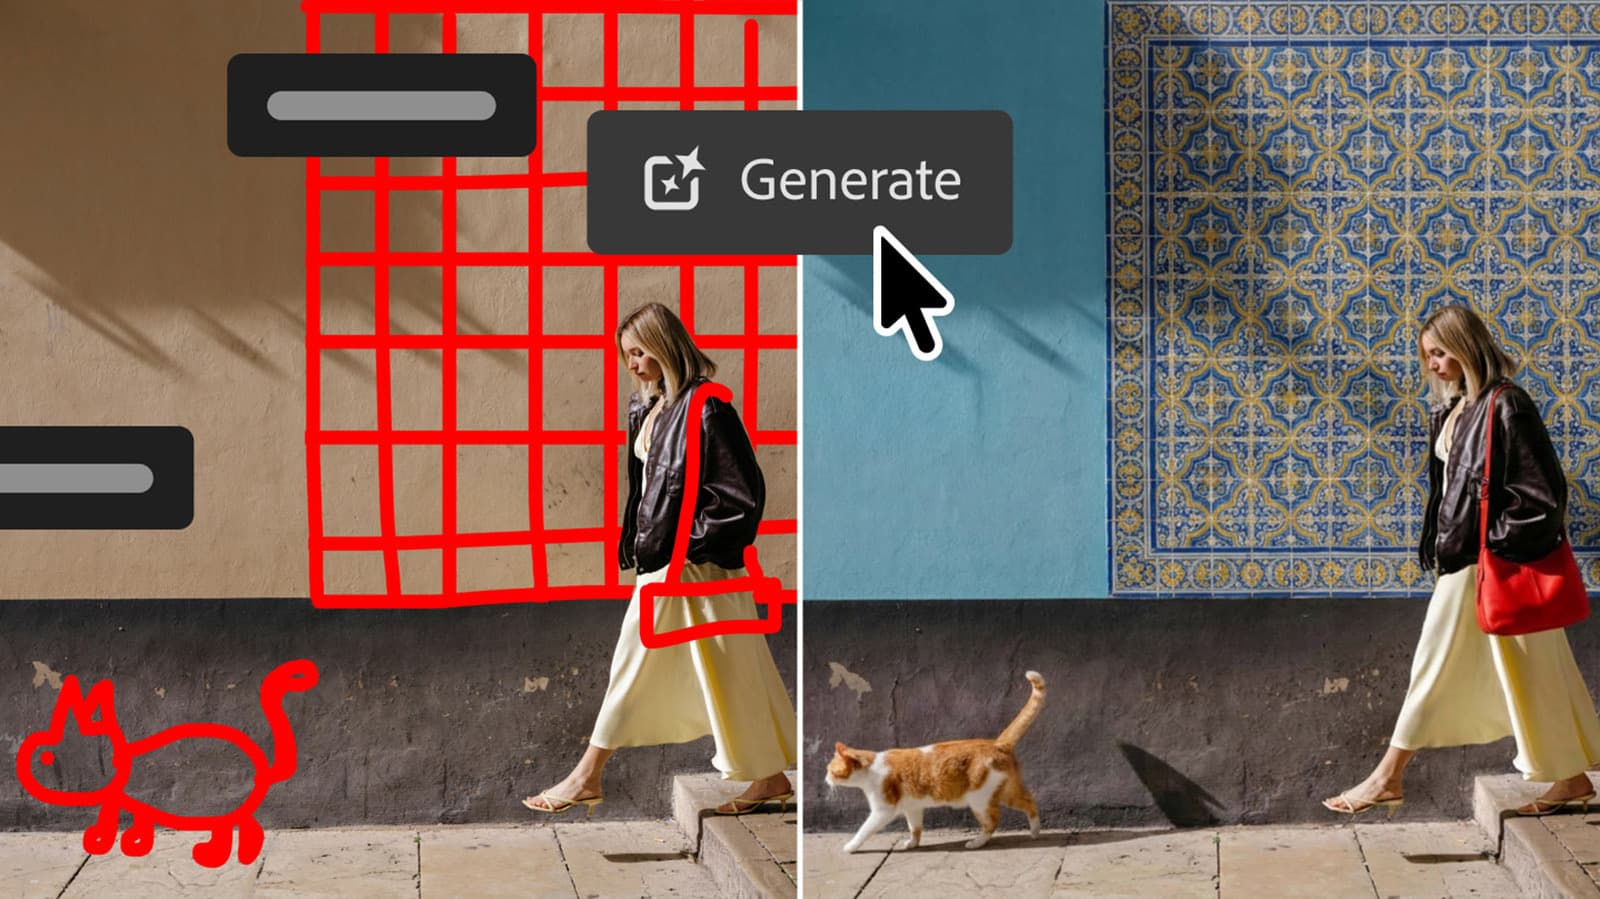
Adobe is updating Photoshop with a dedicated "AI Assisted Editor" view, currently in beta, that consolidates the app's AI tools into a single toolbar. The update also introduces a "markup" feature that lets users draw directly on an image to guide the AI on what to change - no text prompts required.

Photoshop's new 'Markup' feature lets you draw on images to show what you want
Image

Photoshop's new 'Markup' feature lets you draw on images to show what you want

Adobe Photoshop is adding a new "Markup" tool that lets users sketch directly on an image to guide AI-based generation - communicating intent visually rather than through text prompts alone. The update also brings Lightroom-style controls to Photoshop, a long-requested addition for photographers and retouchers who work across both apps.

Your Edit Isn’t Finished Until It Sounds Right
Video

Your Edit Isn’t Finished Until It Sounds Right

Adobe Firefly has expanded into audio with three tools - Generate Music, Generate Speech, and Generate Sound Effects - designed to bring sound into the editing process earlier than traditional workflows allow. Rather than treating audio as a final step after the picture is locked, creators can now use generated sound to test pacing and tone while a project is still taking shape. The tools are integrated into Firefly's broader multi-model creative environment alongside image and video generation.

No image
Multimodal

Z.ai Releases GLM-5.3-Flash: A 320B-A18B Natively Multimodal MoE With a 1M-Token Context

Z.ai has released GLM-5.3-Flash, the first model in the GLM-5 series to handle multiple modalities natively, built on a Mixture-of-Experts architecture with 320 billion total parameters and 18 billion active at inference time. The model supports a context window of just over one million tokens and is available under an MIT license. API access is priced at $0.15 per million input tokens and $0.50 per million output tokens.

No image
Image

Stability AI, maker of image generator Stable Diffusion, raises $76 million in fresh funding

Stability AI, the company behind the open-weight image generation model Stable Diffusion, has secured $76 million in new funding, bringing its total raised to $232 million. The round signals continued investor interest in open-source generative image infrastructure despite a competitive and crowded market. Details on the lead investor and use of funds have not yet been fully disclosed.

Introducing Runway Dev
Multimodal

Introducing Runway Dev

Runway has launched Runway Dev, an API platform giving developers programmatic access to its image, video, and character generation models. The offering is positioned as enterprise-ready from the start, consolidating multiple model capabilities under a single interface. It marks a deliberate move by Runway to expand beyond its consumer and creative-professional tools into the infrastructure layer of AI media production.